Open Source LLMs: आपका Laptop, आपका Server/Cluster और Cloud
एक model family, उसे run करने के तीन तरीके। आपके laptop पर Ollama के साथ। vLLM वाली शक्तिशाली machine पर, जो एक साथ 50 लोगों को serve करती है। और OpenRouter के ज़रिए cloud में, जहाँ सबसे बड़े open models रहते हैं। वही tools, वही idea, तीन scales।
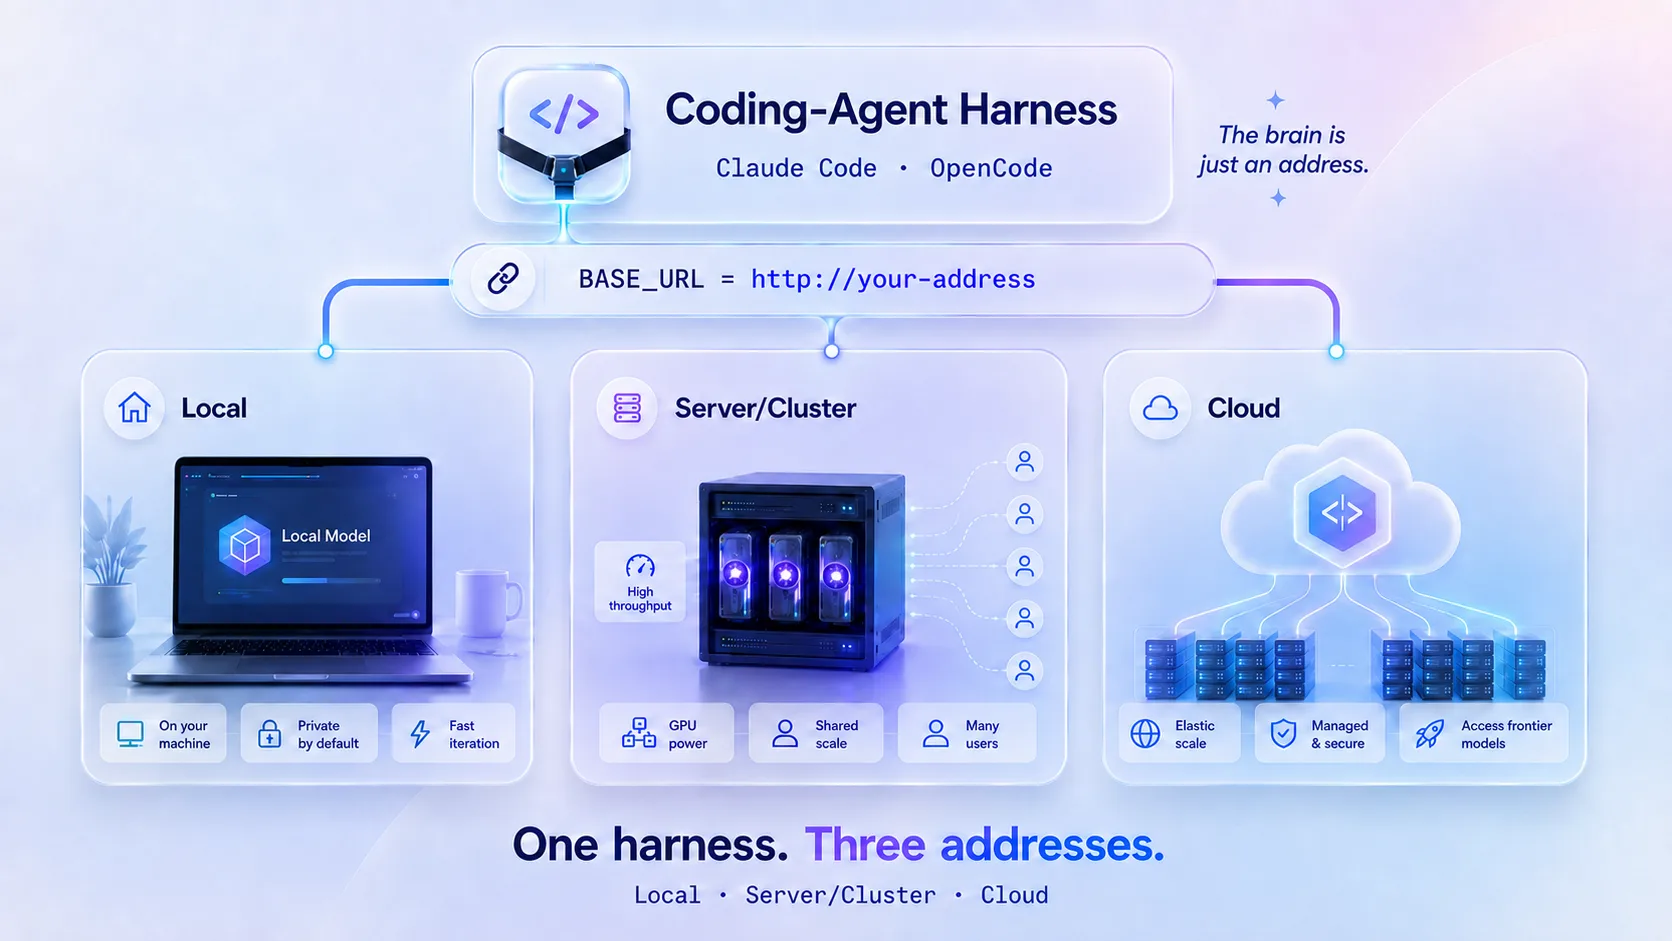
आपने पहले AI का use किया है। आपने box में type किया और उसने जवाब दिया। वह AI आपके computer में नहीं रहता था। वह दूर किसी company की बड़ी machines पर run होता था। आप उसके समय का छोटा हिस्सा rent कर रहे थे।
यह course आपको उपलब्ध choices की पूरी range सिखाता है। Open source models ने खेल बदल दिया: model weights free download किए जा सकते हैं और कोई भी उन्हें run कर सकता है। लेकिन "कोई भी run कर सकता है" एक असली question छिपाता है: उन्हें कहाँ run करें? अपने laptop पर? शक्तिशाली graphics card वाली rented machine पर? या किसी और के cluster पर, क्योंकि model इतना बड़ा है कि वह आपके किसी भी संभावित hardware में नहीं आ सकता?
यही इस course के तीन tiers हैं और हर tier का अपना part है:
| Part | Tier | Serving layer | Scale | आप क्या करेंगे |
|---|---|---|---|---|
| 1 | Local | Ollama | एक व्यक्ति, एक laptop | अपने computer पर model run करके coding agent को उससे जोड़ेंगे |
| 2 | Server/Cluster | vLLM | कई users, एक machine या आपका cluster | उसी Qwen3 8B को 50 concurrent requests पर serve करके बदलाव measure करेंगे |
| 3 | Cloud | OpenRouter (gateway) | Frontier models जिन्हें लगभग कोई host नहीं कर सकता | उन्हीं coding agents से Kimi K3 और DeepSeek V4 Pro चलाएँगे |
तीन tiers, तीन addresses, तीन bills। Laptop: http://localhost:11434 पर Ollama, कोई cost नहीं। Server: http://localhost:8000 पर vLLM, GPU rental की cost; provider के अनुसार 24 GB card के लिए लगभग $0.50 से $2 प्रति hour। Cloud: https://openrouter.ai/api पर OpenRouter, token के हिसाब से cost; यह page लिखते समय प्रति million input tokens लगभग $0.44 (DeepSeek V4 Pro) से प्रति million output tokens $15 (Kimi K3) तक। नीचे आप सीखेंगे कि हर address कब सही choice है। Prices और rentals बदलते हैं, इसलिए budget बनाने से पहले live check करें।
पूरे course के लिए एक picture काम करती है। हर AI tool के दो parts होते हैं। एक part आपकी machine पर रहता है और hands-on काम करता है: harness। दूसरा part सोचने वाला brain है: model। Harness एक address पर brain तक पहुँचता है। Part 1 में address आपका laptop है। Part 2 में वह real graphics card वाली आपके control की machine है। Part 3 में वह trillions of parameters वाले models के आगे खड़ी cloud service है। Harness कभी नहीं बदलता। केवल address बदलता है। इसे एक बार समझें और तीनों tiers एक ही move बन जाते हैं।
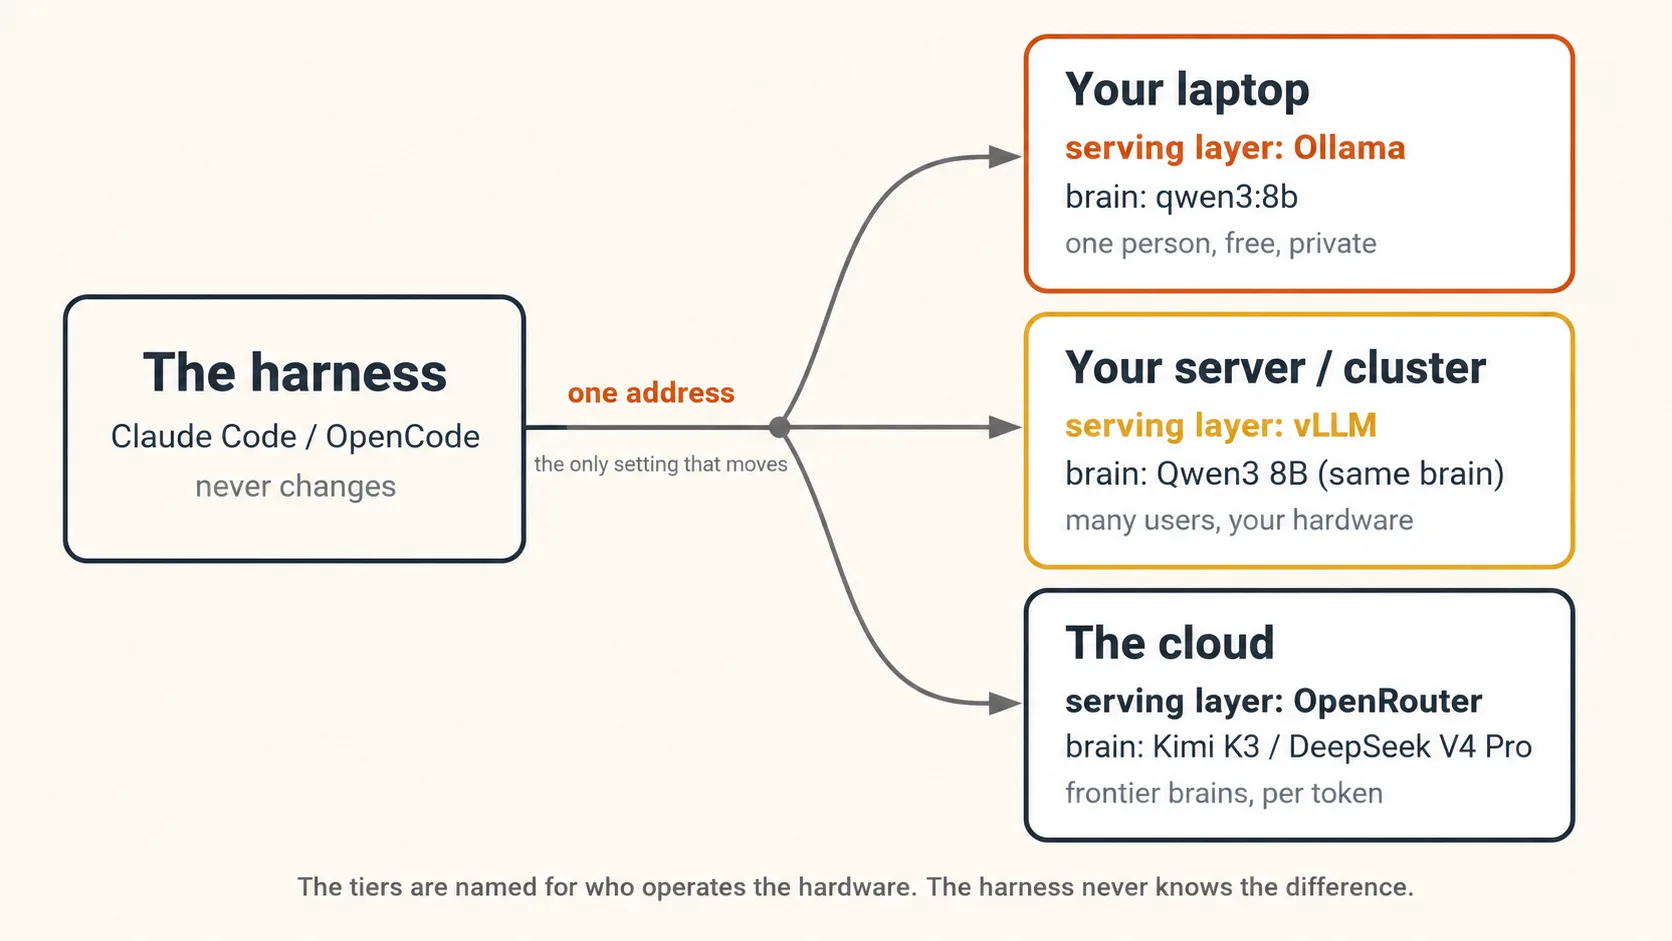
यह General Agents में आपका पहला stop है, जहाँ आप वह AI चुनते हैं जिसे बाकी किताब में चलाएँगे। आप brain को own करने से शुरू करते हैं, क्योंकि इससे section का मुख्य idea पहले दिन से वास्तविक बनता है: agent एक harness और बदल सकने वाले brain का मेल है। इसके बाद agent को अच्छी तरह चलाना (Agentic Coding), लिखी हुई spec से उसे direction देना (Spec-Driven Development) और उसे आपके बिना run होने वाला loop देना (Loop Engineering) सीखेंगे।
अब सीधी भाषा में honest promise और honest limit। Part 1 किसी भी machine पर real, free और private है, हालाँकि सामान्य laptop पर भारी coding work बहुत धीरे चलता है। यह slowness course का bug नहीं है। उसे देखना और कारण समझना Part 1 की मुख्य lesson है। Part 2 के लिए NVIDIA graphics card वाली machine चाहिए, जिसे अधिकतर students कुछ dollars में hour के हिसाब से rent करते हैं। Part 3 के लिए कुछ dollars credit वाला OpenRouter account चाहिए। हर part स्वतंत्र है। आज Part 1 करें और तैयार होने पर बाकी parts के लिए लौटें।
- Part 1, local model से chat: केवल free Ollama install। कोई भी कर सकता है।
- Part 1 का coding half और Parts 2 व 3: पहले से installed coding agent (Claude Code या OpenCode)। अभी नहीं है? Agentic Coding crash course उसे setup कराता है। वह course इसके पहले या बाद में कर सकते हैं।
- केवल Part 2: NVIDIA GPU वाली Linux machine तक access: standard build के लिए लगभग 24 GB GPU memory या compatible hardware पर compressed build के लिए लगभग 16 GB (Part 2 दोनों paths दिखाता है)। Cloud GPU provider से एक-दो hours के लिए rent करना सामान्य और सस्ता है।
- केवल Part 3: free OpenRouter account और कुछ dollars credit।
पहले step से अपने computer पर साथ चल सकते हैं। इस page के commands Bash में हैं, जो macOS, Linux और WSL के ज़रिए Windows पर काम करते हैं। PowerShell use करने पर हर tool के live docs में matching form देखें। Coding-agent वाले हर step में छोटे throwaway git folder के अंदर काम करें, ताकि agent आपकी किसी महत्वपूर्ण चीज़ को touch न कर सके। केवल पढ़ी तीन limits की तुलना में खुद मिली एक limit ज़्यादा सिखाती है।
आसान भाषा में key words
इसे अभी एक बार पढ़ें। कोई word unclear लगे, तो वापस आएँ। नीचे हर concept इन्हें context में फिर सिखाता है, इसलिए यहाँ याद करने की ज़रूरत नहीं।
| Term | आसान अर्थ |
|---|---|
| Model / brain | असली सोच करने वाला AI। आप words भेजते हैं और वह words लौटाता है। |
| Ollama | Free program जो AI model download करके आपके computer पर run करता है। एक व्यक्ति के लिए बना है। |
| vLLM | Free program जो AI model को कई users के लिए एक साथ serve करता है। Shared machine के लिए बना है। |
| Serving layer | Model load करके requests का जवाब देने वाला software। Ollama और vLLM दोनों serving layers हैं। |
| OpenRouter | Cloud gateway जो सैकड़ों models को एक address के पीछे रखता है। पीछे के hosts serving layers चलाते हैं। |
| Harness / tool | Brain के चारों ओर program। वह आपकी files पढ़ता, commands run करता और changes दिखाता है। Claude Code एक harness है। |
| Coding agent | Harness जो आपके लिए code लिखता और edit करता है: Claude Code या OpenCode। |
localhost | ऐसा address जिसका अर्थ "यही computer" है। आपकी machine खुद से बात करती है, इसलिए internet की ज़रूरत नहीं। |
| Address / base URL | Tool अपना work जहाँ भेजता है। उसे localhost पर point करें और work आपकी machine पर रहता है। |
| Tool call | छोटा exact message जिससे model कहता है "इस file को edit करें" या "यह command run करें"। यह data है, sentence नहीं। |
| Token | Model के पढ़ने और billing की unit: word का एक हिस्सा, English के लगभग तीन से चार letters। |
| Context window | Model एक बार में कितने tokens रख सकता है। बहुत छोटा हो, तो task की शुरुआत भूल जाता है। |
num_ctx | Context window की Ollama setting। Default आपकी machine पर निर्भर है और coding agents के लिए अक्सर बहुत छोटा होता है। |
| दो walls | Local coding setup को दो चीज़ें पार करनी हैं: पर्याप्त strong model और पर्याप्त fast hardware। |
| Concurrency | एक समय पर आने वाली requests की संख्या। एक user की concurrency 1 है। Classroom की concurrency 50 है। |
| Throughput | प्रति second कुल useful work, यहाँ सभी users के combined tokens per second में measured। |
| Continuous batching | vLLM की technique: कई requests को GPU में साथ भेजना और बीच में नई requests को खाली slots में डालना। |
| Open-weight model | ऐसा model जिसके trained weights download किए जा सकते हैं। Formal अर्थ में हमेशा "open source" नहीं: training data और कुछ terms बंद रह सकते हैं। |
| Frontier open model | Charts के top पर open-weight model, जो इतना बड़ा है कि केवल clusters उसे serve कर सकते हैं। Kimi K3 एक example है। |
| API key | Secret string जो साबित करती है कि account आपका है। Cloud tier में billing भी इसी से होती है। |
इस course में दो layers साथ चलती हैं और बहुत अलग speed से पुरानी होती हैं। पहली याद रखें। दूसरी lookup करें।
- स्थायी layer। Model तीन scales पर रह सकता है: आपकी machine, आपके control की machine या rented cluster। Tool बदल सकने वाले address पर उस तक पहुँचता है। एक user के लिए बनी serving layer load में queue बनाती है, कई users वाली नहीं। सही tier privacy, hardware और cost पर निर्भर करता है, जिन्हें आप पहले महसूस और फिर नाम देंगे। नीचे के हर command के बदलने के बाद भी यह सच रहेगा।
- Mechanical layer। हर version number, flag, model name, price और setting। Ollama, vLLM, OpenRouter और coding tools तेज़ी से बदलते हैं। इसलिए हर command को live docs का pointer मानें, याद रखने योग्य fact नहीं। Course और current docs में disagreement हो, तो docs सही हैं।
यह course क्या cover करता है
| Concept | Part | आप क्या करेंगे |
|---|---|---|
| 1 | 1 | लगभग दो minutes में अपने computer पर model run करके उससे chat करेंगे |
| 2 | 1 | वह एक idea सीखेंगे जो सब चलाता है: brain केवल एक address है |
| 3 | 1 | Model से काम करवाएँगे: एक command से coding agent को उससे जोड़ेंगे |
| 4 | 1 | Real coding task देकर महसूस करेंगे कि local brain कहाँ टिकता या टूटता है |
| 5 | 1 | दो walls समझेंगे: पर्याप्त strong model और पर्याप्त fast hardware |
| 6 | 1 | Real tool call के अंदर देखेंगे, जिसे weak model गलत करता है |
| 7 | 1 | तय करेंगे कि brain own करना कब सही है |
| 8 | 2 | देखेंगे Ollama one-person kitchen क्यों है: 50 requests भेजकर queue बनते देखेंगे |
| 9 | 2 | उसी Qwen3 8B को vLLM से serve करके continuous batching का अर्थ सीखेंगे |
| 10 | 2 | वही 50 requests vLLM को भेजकर दोनों curves plot और difference पढ़ेंगे |
| 11 | 2 | Claude Code और OpenCode को vLLM server से जोड़ेंगे, translator की ज़रूरत नहीं |
| 12 | 2 | तय करेंगे कि server tier कब सही है |
| 13 | 3 | Frontier open models जानेंगे जिन्हें लगभग कोई self-host नहीं कर सकता: Kimi K3, DeepSeek V4 Pro |
| 14 | 3 | OpenRouter के ज़रिए दोनों को Claude Code और OpenCode से चलाएँगे |
| 15 | 3 | Performance और price में चुनकर हर job के लिए सही tier तय करेंगे |
| 16 | 3 | तीनों tiers के आगे एक router रखकर tier policy को config में बदलेंगे |
| A | Appendix | Part 2 server को keys, budgets और एक menu वाली shared service में बदलेंगे |
📚 Teaching Aid
पूरी presentation देखें: Open Source LLMs: आपका Laptop, आपका Server/Cluster और Cloud
Part 1: Local tier। आपके laptop पर model (Ollama)
इस part की serving layer Ollama है और scale एक व्यक्ति, एक machine है। यहाँ सब free और private है।
1. अपने computer पर brain: यहाँ से शुरू करें
इसे समझने का सबसे तेज़ तरीका एक बार करना है। इसलिए theory से पहले अपने computer पर model run करके उससे बात करें। इस part के लिए code लिखने की ज़रूरत नहीं। कोई भी इसे कर सकता है।
यह करने वाला free program Ollama है। वह AI model download करके आपके computer पर run करता है। अपनी machine वाला तरीका चुनें।
- App (Mac या Windows)
- Terminal (Linux सहित कोई computer)
- ollama.com/download पर जाएँ और सामान्य तरीके से Ollama install करें। इसमें छोटी chat app शामिल है।
- Ollama app खोलें। वह Mac के menu bar या Windows system tray में रहती है।
- ऊपर selector से model चुनें।
gemma3:4bजैसे छोटे model से शुरू करें। पहली बार चुनने पर कुछ GB download होंगे, जिसमें कुछ minutes लगेंगे। - Box में question type करके Enter दबाएँ।
बस इतना ही। Answer आपके computer पर run हो रहे model से आया।
Terminal खोलकर एक command run करें। वह पहली बार model download करती है, फिर chat खोल देती है:
ollama run gemma3:4b
Question type करके Enter दबाएँ। Chat छोड़ने के लिए /bye type करें।
Ollama अभी नहीं है, तो पहले ollama.com/download से install करें और फिर ऊपर वाला command run करें।
कौन-सा model चुनें? छोटे से शुरू करें। छोटा model तेज़ जवाब देता है और सामान्य machine में fit होता है। बाद में बड़े models try कर सकते हैं।
| Model | Approximate download | Comfortable RAM | किसके लिए अच्छा है |
|---|---|---|---|
gemma3:1b | 1 GB से कम | लगभग 4 GB | छोटा और तेज़, लेकिन weak answers |
llama3.2:3b | लगभग 2 GB | लगभग 8 GB | एक solid, छोटी first chat |
gemma3:4b | लगभग 3 GB | लगभग 8 GB | Strong छोटा model, अच्छा default |
qwen3:8b | लगभग 5 GB | लगभग 16 GB | बेहतर answers, अधिक memory चाहिए |
Table का एक model इस part से आगे भी important है: qwen3:8b। Course Part 1 और Part 2 में इसे constant रखता है, ताकि बदलाव होने पर कारण साफ़ हो। Machine में fit होता है, तो अभी pull करें। नहीं, तो यहाँ छोटा model use करें और Part 2 में hardware rent करें।
Models update होने पर ऊपर के exact names और sizes बदलते हैं। किसी tag पर निर्भर होने से पहले ollama.com/library पर check करें। Live source check करने की आदत ही "look it up" layer को लागू करती है।
Concept 1 तब done है जब: आपने question पूछा और अपने computer पर run हो रहे model ने जवाब दिया। Wifi off करके फिर पूछें। वह फिर भी काम करता है। कुछ भी computer से बाहर नहीं गया।
आख़िरी बात पर कुछ देर रुकना सही है। Model आपकी machine पर छोटे program की तरह run होता है और localhost नाम वाले address पर listen करता है। इसका अर्थ "यही computer" है। आपकी machine खुद से बात कर रही है। इसलिए internet off होने पर भी काम चलता है।
अगर आप केवल अपने computer पर private AI चाहते थे, तो वह मिल गया। इसे कभी भी offline और free run कर सकते हैं; type किया कुछ भी computer से बाहर नहीं जाता। केवल यह जानना भी उपयोगी है।
बाकी course उसी local model से काम करवाता है: files पढ़ना, code लिखना और आपके लिए edit करना। यह interesting लगे, तो आगे पढ़ें। नहीं, तो भी win मिल चुकी है।
2. सब चलाने वाला एक idea: brain केवल एक address है
आपने अभी इसे कर लिया। अब जो हुआ उसका नाम रखें, क्योंकि यह idea आपके हर AI tool और course के तीनों tiers के नीचे है। इसे धीरे समझना सही है।
आपके AI tool के दो parts हैं:
- Harness: आपकी machine का program। वह files पढ़ता, commands run करता और बदलाव दिखाता है। Claude Code एक harness है। Ollama chat app उससे सरल harness है।
- Brain: वह model जो सब पढ़कर तय करता है कि क्या कहना या करना है।
Harness उसी तरह address से brain तक पहुँचता है जैसे browser website तक पहुँचता है। इसे phone number समझें। Harness number dial करता है और दूसरी ओर जवाब देने वाला सोचता है।
आमतौर पर यह number दूर company की machines की ओर जाता है। लेकिन यह केवल setting है। Number बदलें और वही harness अब दूसरे brain से बात करता है। Concept 1 में नया number localhost था: आपकी अपनी machine। इसलिए जवाब देने वाला brain आपके laptop वाला था।
Food delivery app की कल्पना करें। Phone की app हर दिन वही रहती है। Restaurant address बदलें और वही app दूसरी kitchen से order करती है। आपका AI tool app है। Address phone number है। उस address वाली kitchen में model answer बनाता है।
यह part आसानी से गलत समझा जाता है और आगे important होगा। Local brain पहले वाले brain की छोटी copy नहीं है। वह अलग brain है और बहुत weak हो सकता है। App वही, kitchen दूसरी, जहाँ cook कम skilled हो सकता है। इसे याद रखें। यह सीधे Concept 5 तक जाता है।
Kitchen वाली picture याद रखें, क्योंकि course तीन kitchens जाता है। Part 1 आपके घर की kitchen है। Part 2 आपकी चलायी industrial kitchen है, जो पूरे restaurant को serve करने के लिए बनी है। Part 3 दुनिया के best restaurants से order करना है, क्योंकि उनकी kitchen किसी घर में नहीं आ सकती। App पूरे समय वही रहती है। केवल address बदलता है।
आपने एक address बदला और अपने computer के model ने answer दिया। AI tool का कौन-सा part बदला और कौन-सा वही रहा? Brain बदला: अब words आपके computer वाले model को जाते हैं। Harness वही रहा: app, buttons और उससे बात करने का तरीका। आपने केवल dial होने वाला address बदला।Answer देखें
3. इससे काम करवाएँ: local brain पर coding agent
Local model से chat अच्छी शुरुआत है। लेकिन agent केवल chat नहीं करता। वह files पढ़ता, code लिखता और आपके लिए commands run करता है। इसलिए coding agent को उसी local brain से जोड़ें।
यह step coding agent को local model से जोड़ता है। इसलिए Claude Code या OpenCode पहले से installed चाहिए। कोई एक है, तो ready हैं। नहीं, तो पहले install करें; Agentic Coding crash course पूरा process दिखाता है। नीचे वाला command उसे connect और launch करता है। वह agent install नहीं करता।
यह करने के दो तरीके हैं। आसान तरीका एक command है। Manual तरीका नीचे की wiring दिखाता है, जिसे एक बार देखना उपयोगी है। Tab चुनें।
- बस run करें
- हाथ से setup करें
Ollama के recent versions settings edit किए बिना coding agent connect और launch कर सकते हैं। एक command:
ollama launch claude
यह Claude Code को local model use करने के लिए setup करके start करता है। वह model पूछेगा या पहले pull किया model name दे सकते हैं:
ollama launch claude --model qwen3:8b
दूसरे tool के लिए matching command है: ollama launch opencode।
unknown command "launch" दिखेollama launch के लिए recent Ollama, version 0.15 या नया चाहिए। Error दिखे, तो Ollama update करें: ollama.com/download से installer फिर run करें या app से update करें। Version ollama --version से check करें।
छोटी companion skill पूरा setup करती है और समय लगाने से पहले hardware की सच्चाई बताती है। Agent उसे पढ़कर काम करता है। Install करें, फिर सामान्य words में कहें:
npx skills add panaversity/local-llm-agentic-coding --agent claude-code opencode -y
मुझे local model पर coding agent चलाने के लिए setup करें। पहले hardware को honestly check करें, फिर step by step guide करें और किसी बड़े action से पहले approval के लिए रुकें।
Installer अनजान name को चुपचाप skip कर सकता है, इसलिए पहले npx skills add panaversity/local-llm-agentic-coding --list से preview कर सकते हैं।
ऊपर वाला command कुछ settings भरता है। अब देखें कि वह क्या भरता है, ताकि wiring समझें और कहीं भी कर सकें। दोनों tools उसी local model से थोड़े अलग तरीके से बात करते हैं।
- Claude Code
- OpenCode
Claude Code local model से ऐसे बात करता है जैसे Anthropic से कर रहा हो। उसे local address पर point करें, placeholder token दें और पक्का करें कि real API key set नहीं है:
export ANTHROPIC_BASE_URL=http://localhost:11434   # the local address, bare host, no /v1
export ANTHROPIC_AUTH_TOKEN=ollama                 # any non-empty word; it is sent as "Bearer ollama"
export ANTHROPIC_API_KEY=                          # must be empty, or it overrides the line above
claude --model qwen3:8b                             # use a model tag you have pulled
कुछ छोटे notes परेशानी बचाते हैं:
- Address bare है, केवल host और port। Claude Code बाकी path खुद जोड़ता है।
/v1न जोड़ें। - Ollama model को
--modelसे नाम देना होगा, वरना Claude Code ऐसे model names खोजेगा जो local machine में नहीं हैं। - Windows पर
localhostगलत जगह point कर सकता है, इसलिए कई लोगhttp://127.0.0.1:11434use करते हैं। यह official docs के बजाय users द्वारा widely reported है।
हर session में settings रखने के लिए उन्हें हर बार type करने के बजाय env block में ~/.claude/settings.json के अंदर रखें:
{
  "env": {
    "ANTHROPIC_BASE_URL": "http://localhost:11434",
    "ANTHROPIC_AUTH_TOKEN": "ollama",
    "ANTHROPIC_API_KEY": ""
  }
}
OpenCode local model से ऐसे बात करता है जैसे OpenAI से कर रहा हो। वह officially local models support करता है। Supported तरीका local server को opencode.json file में describe करना है। इसे एक बार हाथ से करना उपयोगी है, क्योंकि address और model mapping सामने दिखते हैं। आखिर में /v1 देखें। यहाँ यह required है और Claude Code address से एकमात्र difference है:
{
  "$schema": "https://opencode.ai/config.json",
  "provider": {
    "ollama": {
      "npm": "@ai-sdk/openai-compatible",
      "name": "Ollama (local)",
      "options": { "baseURL": "http://localhost:11434/v1" },
      "models": { "qwen3:8b": { "name": "Qwen3 8B (local)" } }
    }
  },
  "model": "ollama/qwen3:8b"
}
इसे project के opencode.json में या सभी projects के लिए ~/.config/opencode/opencode.json में रखें। models के नीचे model name ऐसा tag होना चाहिए जिसे आपने सच में pull किया है। Windows पर 127.0.0.1 use करें, localhost नहीं।
दोनों tool tabs पढ़कर shape देखें। वही model, वही machine, वही port। Claude Code bare address dial करता है। OpenCode उसी address के आखिर में /v1 लगाता है। Local models के लिए दोनों में बस यही difference है। यह contrast सीख लें, फिर किसी tool को किसी local brain से जोड़ सकते हैं। Parts 2 और 3 में इसे बिना बदलाव फिर use करेंगे।
Concept 3 तब done है जब: coding agent शुरू हो गया और उसका model आपके computer वाला है। उससे छोटा question पूछें। Answer आपके laptop से आया, दूर company से नहीं।
यह Concept 2 को real बनाता है। आपने address को localhost किया और वही coding agent अब work आपके computer के brain को भेजता है।
4. अब push करें: real task दें और देखें
Local model का question answer करना छोटा first step है। Local model का real coding work करना असली test है। इसलिए उसे run करें।
थोड़ा real code वाली छोटी throwaway git folder में काम करें, चाहे केवल एक script हो। Agent को local brain पर point करके ऐसा prompt paste करें:
इस folder को देखें। एक छोटा safe improvement खोजें, change करें और दिखाएँ कि क्या बदला।
अब ध्यान से देखें। दो में से एक बात होगी और दोनों lesson हैं।
Strong machine पर, यानी अच्छे graphics card और mid-size model के साथ, यह काम करता है। Local brain files पढ़ता, plan बनाता, edit करता और clean change दिखाता है। उस पल free, offline और private वास्तविक बनते हैं। यह आपका setup है और काम कर रहा है।
सामान्य laptop पर, यानी graphics card के बिना छोटे model के साथ, wall महसूस होती है। हर step में minutes लग सकते हैं, क्योंकि machine बहुत सारा text धीरे पढ़ती है। या run बीच में bad tool call error के साथ रुक सकता है। Brain ने "इस file को edit करें" कहना चाहा, लेकिन format गलत कर दिया।
अभी कुछ fix न करें। बस देखें कि क्या हुआ और कैसा लगा। Fast और clean? या slow या broken? वही feeling अगले concept का raw material है।
Task धीरे चला या टूटा, तो कुछ गलत नहीं हुआ। आपने छोटी machine पर बड़ा model run करने की honest limit देखी। Money या time लगाने से पहले यह जानना real और useful है। अगला concept वही feeling समझाता है।
Concept 4 तब done है जब: आपने local brain से real code change माँगा और result देखा, चाहे clean edit, लंबा wait या broken run मिला।
5. वह क्यों टिका या टूटा: दो walls
अब explanation, क्योंकि आपने वह चीज़ महसूस कर ली जिसे यह समझाता है। Part 1 का सबसे important idea साफ़ भाषा में समझें।
Local coding agent को दो अलग walls पार करनी होती हैं। वे एक wall नहीं हैं और एक का fix दूसरे के लिए कुछ नहीं करता।
पहली wall capability है। जब model act करता है, और coding work में लगभग हर turn पर करता है, तो उसे valid tool call लिखनी होती है। यानी "इस file को edit करें, इस line को उस line से बदलें" उस exact strict format में कहना जिसे harness expect करता है। छोटे models अक्सर इसे गलत करते हैं। Tool skip कर देते हैं या format बिगाड़ देते हैं, फिर run रुक जाता है। Tool use के लिए trained strong model आमतौर पर इसे fix करता है। Faster hardware नहीं: fast machine पर tiny model फिर भी broken tool calls लिखता है।
दूसरी wall throughput है। हर turn में harness आपके task के शुरू होने से पहले model को लंबी instruction भेजता है, जिसमें tool rules और वह जो कर सकता है उनकी definitions होती हैं। Machine को सब तेज़ी से पढ़ना पड़ता है। Graphics card के साथ एक moment लगता है। उसके बिना केवल processor पर हर turn minutes ले सकता है। Graphics card इसे fix करता है। Smarter model नहीं: slow machine पर brilliant model भी बहुत slow है।
| Wall | क्या चाहिए | किससे fix होती है | किससे fix नहीं होती |
|---|---|---|---|
| Capability | Act करते समय सही tool call | Tool use trained strong model | केवल faster hardware |
| Throughput | लंबी instruction को seconds में पढ़ना | Graphics card (GPU) | Smarter, smaller model |
नीचे की table से पहले size पर honest note: reliable tool use के लिए universal parameter-count floor नहीं है। Tool-use training, chat template और harness fit raw size जितने important हैं। अच्छी तरह trained छोटा model खराब trained बड़े model को हरा सकता है। फिर भी आज के common local models में rough pattern है कि बड़े models multi-step tool use को ज़्यादा reliably handle करते हैं। इस page की tables वही pattern बताती हैं।
Cheap machines दोनों walls एक साथ miss करती हैं। इसलिए सामान्य laptop model से chat के लिए ठीक है, coding agent run करने के लिए नहीं: wiring सही है, लेकिन कोई wall clear नहीं हुई।
Concept 2 की kitchen के अंदर zoom करें। Meal दो चीज़ें तय करती हैं: cook और stove। Cook model है। Stove machine है। Capability पूछती है कि cook हर बार सही order बनाने के लिए skilled है या नहीं। Throughput पूछती है कि stove minutes के बजाय seconds में serve करने जितना fast है या नहीं। Slow stove पर great cook फिर भी wait कराता है। Fast stove पर clumsy cook dish फिर भी बिगाड़ता है। दोनों चाहिए।
Hardware पर एक honest sentence याद रखें। इस page की हर चीज़ graphics card वाली rented cloud machine पर वही है: wiring, settings, दो walls। केवल speed बदलती है। लगभग 16 से 24 GB memory वाला graphics card local setup को सच में usable coding agent बना देता है। यही Part 2 का doorway है, जहाँ वैसी machine rent करके वह करेंगे जो laptop कभी नहीं कर सकता।
कौन-सा model किस machine में fit होता है, उसकी rough guide:
| Model | Size | ज़रूरी memory | Coding work के लिए ready? |
|---|---|---|---|
llama3.2:3b | 3B | लगभग 8 GB | नहीं। Chat के लिए अच्छा, tool calls बिगाड़ता है। |
qwen3:8b | 8B | लगभग 16 GB | Simple tasks के लिए ठीक |
phi4:14b | 14B | लगभग 12 GB | इस lineup में practical floor के आसपास |
qwen3:30b-a3b | 30B mix | लगभग 20 से 24 GB | Best balance: strong answers, फिर भी quick |
qwen3:32b | 32B | लगभग 24 GB | Strong, ऊपर वाले mix से थोड़ा slow |
Task run हुआ, लेकिन हर turn में four minutes लगे। उसी laptop पर बहुत smarter model लगा देते हैं। क्या वह fast होगा? नहीं। Slow turn throughput wall है और smarter model उसे नहीं बदलता। Smarter model बड़ा होने के कारण और slow भी हो सकता है। Throughput graphics card से fix होती है, model choice से नहीं। दोनों walls को मिलाना वही गलती है जिसे यह concept रोकता है।Answer देखें
6. अंदर देखें: tool call असल में क्या है
Concept 5 ने कहा weak model "tool calls बिगाड़ता है"। यह vague लगता है। Real tool call देखें, क्योंकि उसे देखकर पूरी बात साफ़ होती है।
Healthy tool call सामान्य writing नहीं है। यह structured data का छोटा piece, exact instruction है जिसे harness execute कर सकता है। वह ऐसी दिखती है:
{
  "type": "tool_use",
  "name": "edit_file",
  "input": { "path": "README.md", "old": "Hello", "new": "Hello, world" }
}
Harness इसे पढ़कर file edit करता है। Model ने change खुद नहीं लिखा। उसने precise instruction भेजी और harness ने काम किया। "Model tools use करता है" का असली अर्थ यही है। इसी moment chat model chat box से act करने वाली चीज़ बनता है।
अब देखें कि बहुत weak model क्या करता है। वह input को real object के बजाय text blob की तरह भेजता है और harness उसे ऐसे validation error से reject करता है:
invalid tool arguments: expected object, got string
Exact wording harness के अनुसार बदलती है। Failure का shape important है: arguments गलत structure में आए, इसलिए harness उन पर act करने से मना करता है।
Run रुक जाता है। कुछ edit नहीं होता। यही एक बिगड़ा message अक्सर Concept 4 वाला run खत्म करता है। यह capability wall को पास से देखना है।
एक और चीज़ तय करती है कि यह काम करेगा या नहीं: context window। यह model के एक बार में रखने वाले tokens की संख्या है; token word का piece और models की असली counting unit है। Ollama में इसे num_ctx set करता है। Harness हर turn लंबी instruction भेजता है और Ollama आपकी machine की graphics memory से default window चुनता है। अधिकतर laptops में 24 GiB से कम VRAM होने पर default केवल 4,096 tokens है। इतनी छोटी window अधिकतर instruction को चुपचाप काट देती है। Trap यह है: कोई error नहीं आता। Ollama instruction trim करके फिर भी answer देता है। Chat ठीक लगता है, लेकिन coding tasks confusing तरीके से fail होते हैं, क्योंकि model ने tool-call format बताने वाला part देखा ही नहीं। Truncated window इस pattern का सबसे common cause है, पर अकेला नहीं। इसलिए पहले इसे check करें, assume नहीं।
Fix window बड़ी करना है। Agents और coding tools के लिए Ollama की current guidance कम-से-कम 64,000 tokens है। Agent run होने पर उससे बस कह सकते हैं:
Context window बहुत छोटी लग रही है और tool calls तोड़ रही है। इसे कम-से-कम 64,000 पर set करके task फिर try करें।
गहराई से: छोटी window बिना warning चीज़ें क्यों तोड़ती है
Context window को 64,000 tokens या अधिक करना "मेरा local coding agent broken है" का सबसे common fix है। इसे कई तरीकों से set कर सकते हैं: Ollama app settings में slider, server को OLLAMA_CONTEXT_LENGTH=64000 से शुरू करके, custom model file (Modelfile में PARAMETER num_ctx 64000) या chat session में /set parameter num_ctx 64000 से। बड़ी windows को अधिक memory चाहिए और ollama ps दिखाता है कि running model को वास्तव में कौन-सी window मिली। Setup chat answer करता लेकिन real tasks fail करता है, तो पहले context window check करें।
Quick fix list खोलें
- Chat answer करता है, लेकिन real tasks की instructions ignore करता है। Context window शायद बहुत छोटी है, इसलिए instructions कट गईं। दूसरे causes खोजने से पहले
num_ctxको 64,000 या अधिक करके retest करें। - हर turn minutes लेता है, फिर timeout होता है। Machine लंबी instruction समय पर पढ़ने के लिए slow है।
export API_TIMEOUT_MS=1200000से timeout बढ़ा सकते हैं। फिर भी timeout हो, तो throughput wall सच बता रही है। - Missing key या connectors off होने का message। Harmless है। आपने placeholder token set किया है और local model वे features use नहीं करता, इसलिए दिखता है।
इन्हें याद करने की ज़रूरत नहीं। Agent किसी भी fix में guide कर सकता है।
Concept 6 तब done है जब: आपने real tool call को structured data की तरह देखा और समझते हैं कि बिगड़ी call या बहुत छोटी context window local coding agent को तोड़ती है।
7. Brain own करना कब सही है
अब इसे run कर सकते हैं। Honest question है कि कब करना चाहिए।
Cloud में बड़ा model rent करना या coding agent को normal तरीके से use करना आमतौर पर आसान और अक्सर smarter है। इसलिए local कुछ specific cases में जीतता है, जिन्हें साफ़ समझना सही है:
- Privacy। Work machine से बाहर नहीं जाता। Sensitive या regulated काम में यही decision तय कर सकता है।
- Offline। Network, account या outage नहीं। Disk वाला model plane या locked-down firewall के पीछे भी काम करता है।
- Cost, जब work पूरा दिन चले। किसी service पर single request सस्ती है। लेकिन पूरे month हर few minutes चलने वाला loop अलग bill है। Work कभी न रुके, तो brain own करना cloud से सस्ता हो सकता है।
आख़िरी बात किताब में दो बार important है। Loop Engineering में ऐसे agents बनाएँगे जो पूरा दिन खुद run और आपके सोते समय अपना work check करते हैं। वहीं किसका brain loop चलाता है और हर run कितना cost करता है, detail नहीं design बन जाता है। आपने अभी वह brain own करना सीखा।
एक और बात देखें, जो इस पूरे part की quiet lesson है। Companion skill use की, तो हाथ से setup नहीं किया। आपने skill install की और agent ने use किया। Skill केवल SKILL.md file वाली folder है, वही shape जो skills crash course में सीखी। यानी अपने knowledge को वैसे package और किसी agent के install करने के लिए share कर सकते हैं। Publish करने के लिए ready हों, तो gh skill publish --dry-run ship करने से पहले Agent Skills spec के against check करता है।
Part 1 पूरा है। आप brain own करते हैं, दो coding agents को उससे जोड़ चुके हैं और usability तय करने वाली दो walls जानते हैं। लेकिन बनाई चीज़ पर ध्यान दें: kitchen ने ठीक एक customer को serve किया। आपको। एक साथ 10 requests भेजें और वह line में wait कराएगी। वही line और उसे हटाने वाला software Part 2 है।
Part 2: Server tier। एक machine, कई users (vLLM)
इस part की serving layer vLLM है और scale एक शक्तिशाली machine पर कई users है। Model नहीं बदलता। यही पूरा point है।
सबसे पहले इस part का नया word नाम दें: serving layer। यह model को memory में load और requests का answer देने वाला software है। Ollama serving layer है। vLLM serving layer है। इस part में brain constant, Qwen3 8B, रखते हैं और नीचे की केवल serving layer बदलते हैं। Practice जितना संभव बनाए, बाकी सब fixed रखें, एक चीज़ बदलें और measured difference मुख्य रूप से उसी का होगा। यह केवल good science नहीं। पूरे career में agent systems ऐसे debug करेंगे: variable isolate करें, फिर measure करें। Honest caveat भी साथ है: यह teaching experiment है, laboratory नहीं। Model precision, runtime code और configuration के छोटे differences साथ आते हैं, इसलिए claim expected pattern है, defend करने वाला decimal नहीं।
NVIDIA graphics card वाली Linux machine। नीचे के standard full-precision build के लिए लगभग 24 GB GPU memory रखें या compressed FP8 build के साथ 16 GB card use करें; Concept 9 दोनों paths दिखाता है। लगभग किसी के पास ऐसी machine नहीं होती और ठीक है: cloud GPU provider से एक-दो hours rent करने में कुछ dollars लगते हैं और हर command rented machine पर समान है। अभी rent नहीं कर सकते, तो भी part पढ़ें। आखिर की दो curves खुद draw करने से पहले भी समझने योग्य हैं।
8. एक व्यक्ति की kitchen: Ollama पर 50 requests भेजकर देखें
Part 1 एक claim पर खत्म हुआ: Ollama setup एक customer serve करता है। इसे slogan नहीं, measurement से prove करें।
Experiment यह है। छोटी script लिखेंगे जो model server पर कई requests एक समय पर भेजकर दो numbers report करती है: पूरा batch कितना समय लेता है और सभी requests का combined total tokens per second। एक साथ आने वाली requests की संख्या concurrency है। एक user की concurrency 1 है। एक साथ Enter दबाते 50 students की classroom concurrency 50 है।
Ollama और vLLM एक standard request format, OpenCode config वाला OpenAI-compatible format, answer करते हैं। इसलिए एक script दोनों test करती है। केवल address और model name बदलते हैं। इसे bench.py के रूप में save करें:
# bench.py: fire N concurrent requests at a model server and measure throughput.
# usage: python bench.py <base_url> <model> <concurrency>
import asyncio, sys, time
import httpx

BASE_URL = sys.argv[1]        # http://localhost:11434/v1 (Ollama) or http://localhost:8000/v1 (vLLM)
MODEL = sys.argv[2]           # qwen3:8b (Ollama) or Qwen/Qwen3-8B (vLLM)
N = int(sys.argv[3])          # how many requests at once

PROMPT = "Explain in about 200 words how a bank reconciliation works."

async def one_request(client):
    r = await client.post("/chat/completions", json={
        "model": MODEL,
        "messages": [{"role": "user", "content": PROMPT}],
        "max_tokens": 300,
        "temperature": 0,
    })
    r.raise_for_status()
    return r.json()["usage"]["completion_tokens"]

async def main():
    async with httpx.AsyncClient(base_url=BASE_URL, timeout=3600) as client:
        await one_request(client)   # warm-up: load the model before timing anything
        start = time.perf_counter()
        results = await asyncio.gather(*[one_request(client) for _ in range(N)],
                                       return_exceptions=True)
        wall = time.perf_counter() - start
    ok = [r for r in results if isinstance(r, int)]
    failed = len(results) - len(ok)
    total = sum(ok)
    print(f"concurrency={N}  ok={len(ok)}  failed={failed}  tokens={total}"
          f"  time={wall:.1f}s  throughput={total/wall:.1f} tok/s")

asyncio.run(main())
ज़रूरी एक dependency install करें (pip install httpx), पक्का करें कि Ollama qwen3:8b pull करके run हो रहा है और run reproducible बनाने के लिए एक setting pin करें। Ollama के parallel slots machine के अनुसार बदलते हैं और fair experiment अपनी settings बताता है। Ollama server को OLLAMA_NUM_PARALLEL=4 ollama serve से restart करें (PowerShell: $env:OLLAMA_NUM_PARALLEL=4; ollama serve), ताकि आपकी और classmate की curve same rules से आए। फिर sweep run करें। इसे rented GPU machine पर करें, ताकि Part 2 comparison fair हो: दोनों serving layers के लिए same hardware।
python bench.py http://localhost:11434/v1 qwen3:8b 1
python bench.py http://localhost:11434/v1 qwen3:8b 5
python bench.py http://localhost:11434/v1 qwen3:8b 10
python bench.py http://localhost:11434/v1 qwen3:8b 25
python bench.py http://localhost:11434/v1 qwen3:8b 50
हर concurrency level तीन बार run करके तीनों throughput की median लिखें, ताकि one-off hiccup data point न बने। Concept 10 के plot के लिए वे पाँच medians चाहिए।
अब result पढ़ें। Concurrency 1 पर ठीक था। बढ़ाने पर total throughput लगभग नहीं बदला, लेकिन wall-clock time लंबा होता गया। 50 पर batch ने शायद कई minutes लिए। अंदर simple बात हुई: Ollama कुछ requests parallel run करता है, यानी OLLAMA_NUM_PARALLEL slots जिन्हें अभी 4 pin किया, और बाकी सबको queue में रखता है। Request number 40 slot खुलने तक शुरू नहीं होती। Machine का सबसे expensive part, graphics card, batch का अधिकतर समय queue के साथ wait करता है।
यह Ollama की flaw नहीं है। यह honest design choice है: Ollama एक व्यक्ति के laptop को comfortable बनाने के लिए बना है। Restaurant बनने के लिए कभी नहीं बना।
यह एक cook और दो burners वाली home kitchen है। एक dinner guest, बढ़िया। 50 guests हों, तो 45 order slip लेकर hallway में खड़े हैं। Cook lazy नहीं और stove broken नहीं। Kitchen crowd के लिए design ही नहीं हुई।
Concept 8 तब done है जब: Ollama पर concurrency 1, 5, 10, 25 और 50 के पाँच measured throughput numbers हैं और आपने queue को अपनी आँखों से बनते देखा।
9. Industrial kitchen: उसी brain को vLLM से serve करें
अब दूसरी serving layer। vLLM एक free open source program है जिसका एक काम है: graphics card waste किए बिना model को कई users के लिए एक साथ serve करना। यह UC Berkeley research से आया और अब companies के open models production में serve करने का standard तरीका है। Ollama एक व्यक्ति की comfort optimize करता है, vLLM total throughput।
वह throughput दो ideas से मिलता है, जिन्हें simple words में जानना useful है:
- Continuous batching। Graphics card कई काम एक साथ करने में best है। इसलिए vLLM कई requests साथ भेजता है। Clever part यह है: एक request खत्म होते ही waiting request दूसरों को रोके बिना बीच stream में उसकी slot में आती है। Queue में work हो, तो card idle नहीं रहता। इसकी तुलना उस queue से करें जहाँ card कुछ requests serve करके खत्म करता, फिर अगली उठाता है।
- Paged memory (PagedAttention)। हर active conversation को card की working memory चाहिए। पुराने servers हर conversation के लिए बड़ा block reserve करते थे, जो अधिकतर empty रहता। इसलिए card सच में full होने से पहले "full" दिखता था। vLLM memory को छोटी pages में काटकर केवल ज़रूरत पर देता है, जैसे operating system RAM manage करता है। Result: same card पर एक साथ बहुत अधिक conversations fit होती हैं।
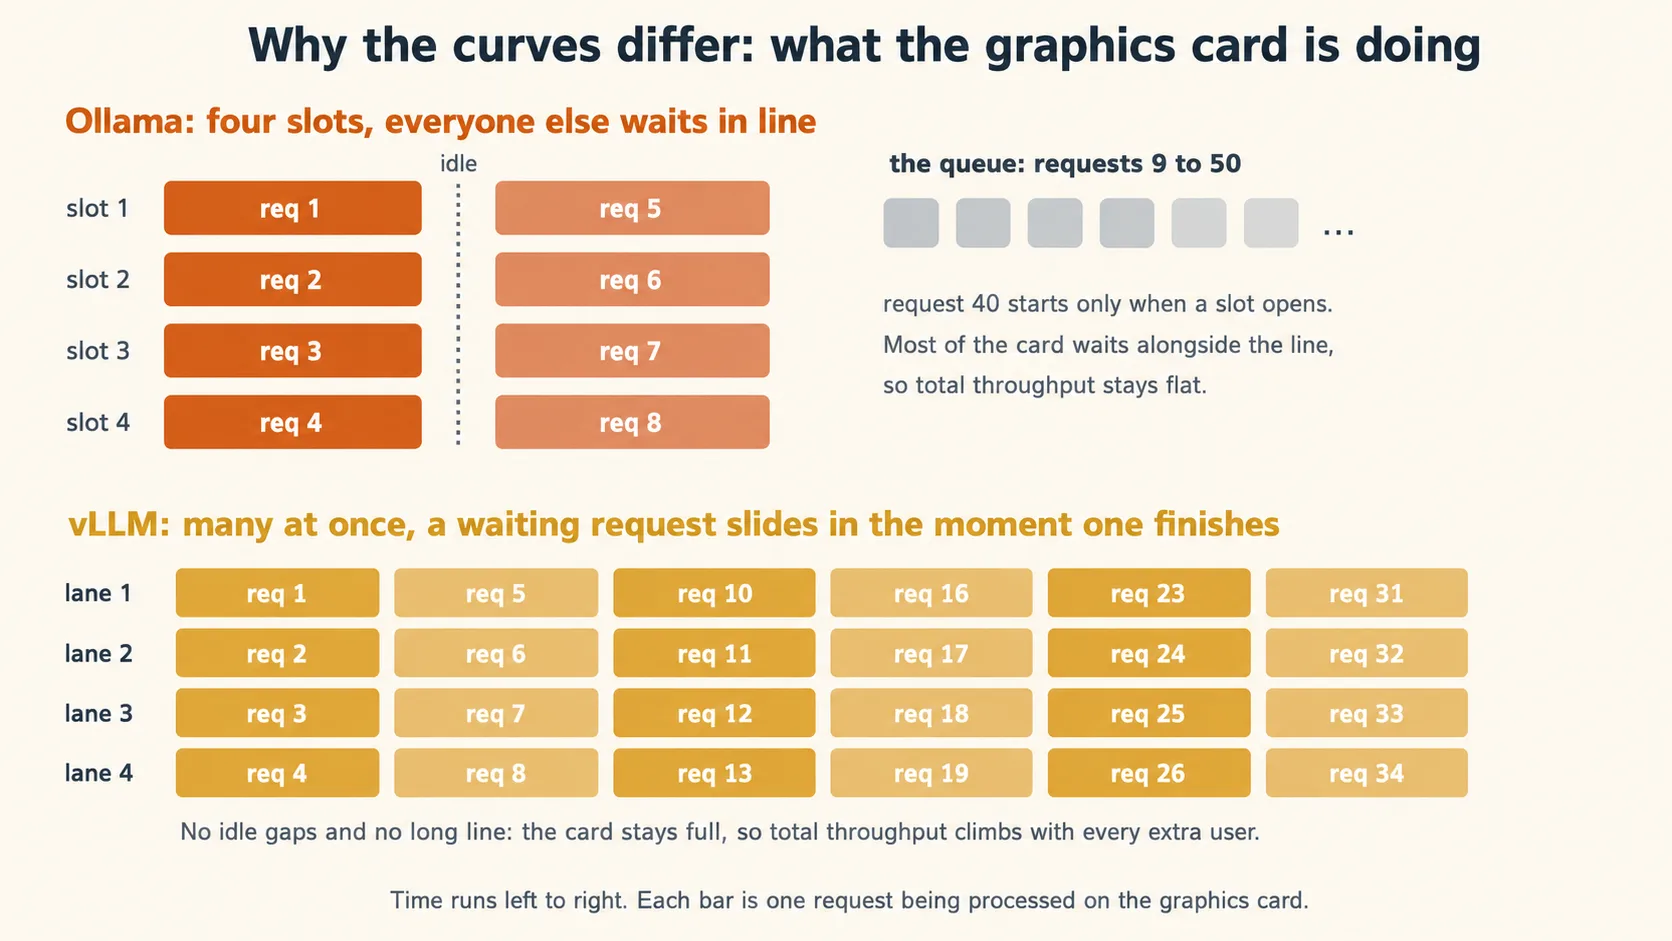
Mechanism names याद रखने की ज़रूरत नहीं। Effect याद रखें: card full रहता है, इसलिए अधिक users आने पर total throughput बढ़ता है, queue नहीं बनती।
एक और बात, ताकि tier names mislead न करें। यह part vLLM को single machine पर run करता है, लेकिन vLLM वहीं नहीं रुकता: वह एक model को कई graphics cards और cluster की तरह काम करती कई machines में फैला सकता है। यह अलग product नहीं, बड़ा scale वाला same software है। Part 3 में rent किए कई professional hosts अपने clusters पर यही चलाते हैं। इसलिए tiers के नाम hardware कौन operate करता है से आते हैं, software क्या कर सकता है उससे नहीं। Part 2 में एक server पर vLLM operator आप हैं। Part 3 में 64 stoves पर कोई और operator है और उनकी kitchen के भी vLLM चलाने की अच्छी संभावना है।
अब run करें। GPU machine पर vLLM install करके अभी test किए model का counterpart serve करें। Names पर note: Ollama और vLLM अलग libraries से models download करते हैं, इसलिए same brain के दो names हैं। Ollama library में qwen3:8b, Hugging Face पर Qwen/Qwen3-8B है, जहाँ से vLLM models लेता है। Variable isolate करने के promise के कारण honest note भी है। दोनों copies byte-for-byte same नहीं: Ollama tag weights की compressed (quantized) copy देता है ताकि laptops में fit हो; vLLM full-precision original download करता है। इसलिए "same brain" को precise पढ़ें: same Qwen3 8B model के दो serving-specific builds, Ollama वाली lighter copy। Precision difference numbers के साथ चलने वाला एक और variable है, लेकिन experiment का throughput pattern नहीं बदलता। Closest match के लिए vLLM side पर compressed build भी serve करें: same flags के साथ vllm serve Qwen/Qwen3-8B-FP8।
pip install vllm

vllm serve Qwen/Qwen3-8B \
  --enable-auto-tool-choice \
  --tool-call-parser hermes \
  --reasoning-parser qwen3
Run से पहले hardware note। Full-precision 8B build को केवल weights के लिए लगभग 16 GB GPU memory चाहिए, conversation working memory से पहले। Comfortable run के लिए लगभग 24 GB card चाहिए। 16 GB card पर compressed build serve करें: model name Qwen/Qwen3-8B-FP8 करें और same flags रखें। pip install vllm driver और CUDA versions पर machine से लड़ता है, तो official vLLM Docker image सबसे reproducible install path है; vLLM docs उसे cover करते हैं।
First run model download करके server को http://localhost:8000 पर start करता है। दो tool flags दिखने से अधिक important हैं: tool-call parser के साथ --enable-auto-tool-choice vLLM को model output से Concept 6 की clean structured tool calls बनाने देता है। उन्हें छोड़ें और coding agents चुपचाप fail होंगे, क्योंकि server harness के execute करने योग्य tool call नहीं बनाएगा। सही parser name model family के अनुसार बदलता है। hermes Qwen3 models का standard है। दूसरा model serve करने पर vLLM tool calling docs check करें।
एक request से prove करें कि यह up है:
curl http://localhost:8000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"model": "Qwen/Qwen3-8B", "messages": [{"role": "user", "content": "Say hello in one line."}]}'
अभी type किए content को देखें। localhost, port 8000, /v1/chat/completions। यह पूरे course वाला address shape है। Brain नहीं बदला। Address के पीछे kitchen बदली।
Concept 9 तब done है जब: vLLM machine पर Qwen3 8B serve करके curl request answer करता है और आप एक-एक sentence में continuous batching व paged memory का benefit बता सकते हैं।
10. Reveal: वही 50 requests, दो curves
सब तैयार है। Same machine। Same brain। Same script। Same 50 requests। केवल serving layer अलग है। vLLM पर वही sweep run करें:
python bench.py http://localhost:8000/v1 Qwen/Qwen3-8B 1
python bench.py http://localhost:8000/v1 Qwen/Qwen3-8B 5
python bench.py http://localhost:8000/v1 Qwen/Qwen3-8B 10
python bench.py http://localhost:8000/v1 Qwen/Qwen3-8B 25
python bench.py http://localhost:8000/v1 Qwen/Qwen3-8B 50
ख़ास तौर पर concurrency 50 batch देखें। Ollama पर कई minutes तक फैला wall-clock time collapse होना चाहिए: 50-request batch pinned Ollama configuration से काफ़ी जल्दी पूरा होता है और answers shifts के बजाय पास-पास आते हैं।
अब picture draw करें, क्योंकि Part 2 से यही एक चीज़ साथ रखनी है। इस script में अपने 10 measured numbers डालें (pip install matplotlib अगर needed हो) और run करें:
# plot.py: tokens per second against concurrency, one line per serving layer.
import matplotlib.pyplot as plt

concurrency = [1, 5, 10, 25, 50]
ollama_tps = [0, 0, 0, 0, 0]   # your five Ollama numbers from Concept 8
vllm_tps = [0, 0, 0, 0, 0]     # your five vLLM numbers from this concept

plt.plot(concurrency, ollama_tps, marker="o", label="Ollama (qwen3:8b)")
plt.plot(concurrency, vllm_tps, marker="o", label="vLLM (Qwen/Qwen3-8B)")
plt.xlabel("Concurrent requests")
plt.ylabel("Total throughput (tokens/sec)")
plt.title("Same model, same machine, two serving layers")
plt.legend()
plt.savefig("two-curves.png", dpi=200)
आपको दो curves मिलती हैं। Ollama line लगभग flat रहनी चाहिए: users जोड़ने से throughput नहीं बढ़ता, मुख्य रूप से queue लंबी होती है, इसलिए हर user का share घटता है। vLLM line climb करनी चाहिए: हर नया user throughput जोड़ता है, पहले तेज़ी से, फिर graphics card के सच में full होने पर मुड़ती है। Exact numbers card, versions और settings पर depend करते हैं और किसी दूसरे से match नहीं होंगे। Shapes अक्सर match करेंगी, और shapes ही lesson हैं। एक habit run को anecdote के बजाय evidence बनाती है: numbers के पास card, driver, Ollama और vLLM versions लिखें, ताकि अलग hardware का अलग result mystery नहीं, finding हो।
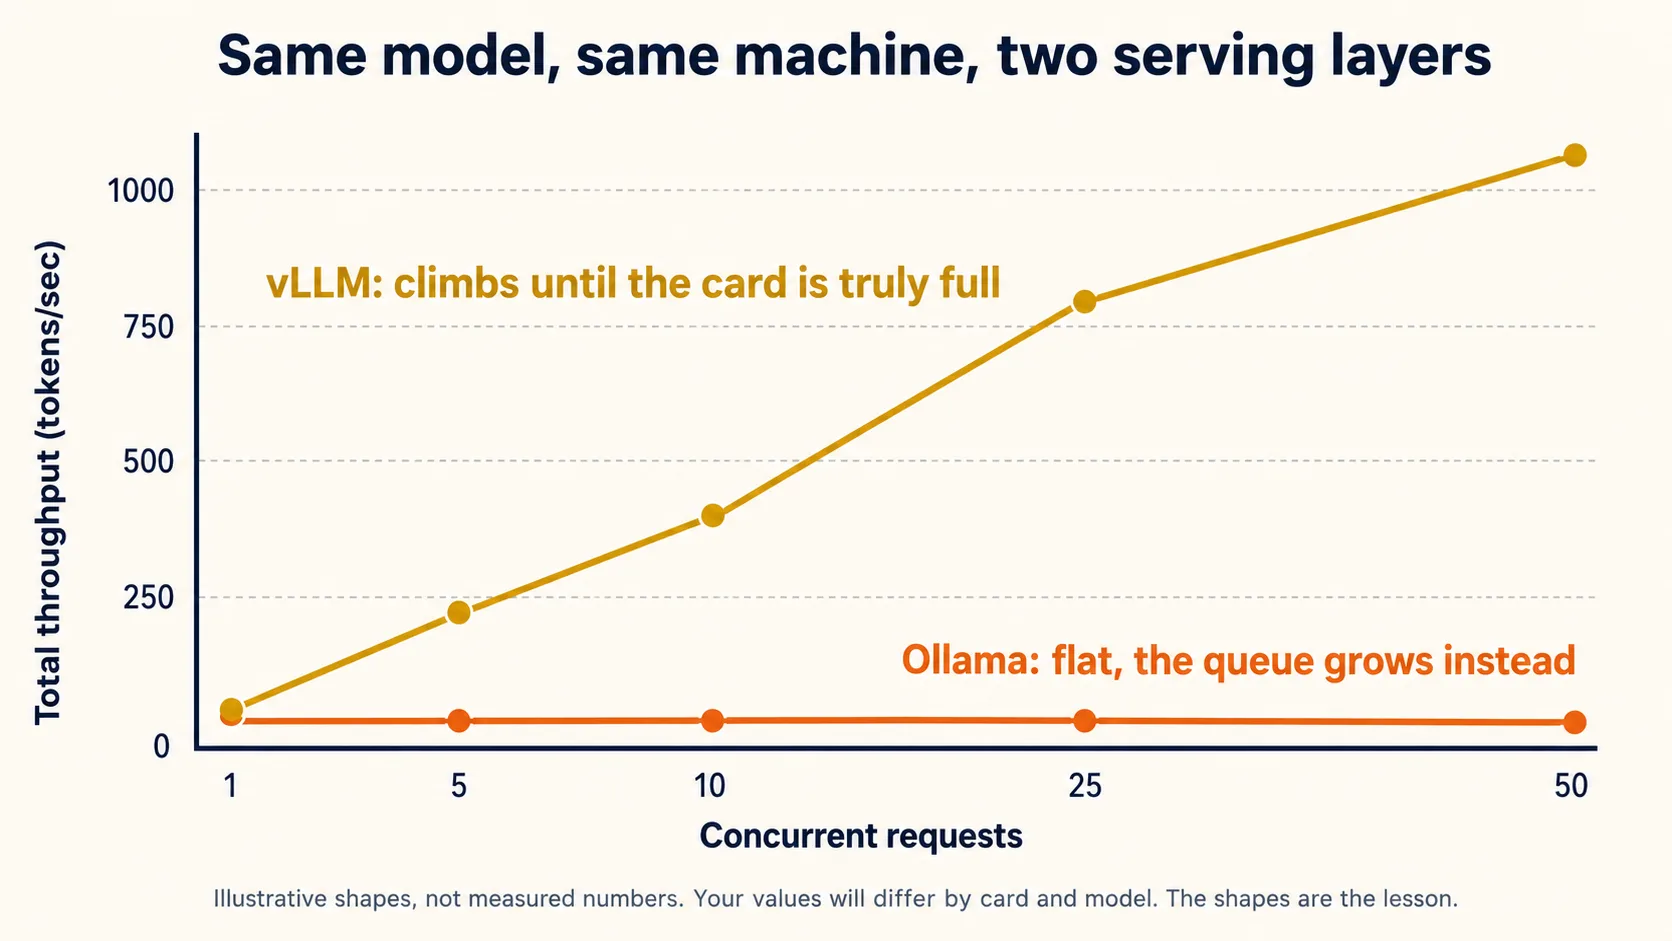
ऊपर की picture expected shapes दिखाती है, real measurements नहीं। आपके 10 numbers से बना आपका chart ही महत्वपूर्ण है।
अब curves के gap को precisely कहें। Hardware नहीं: same card। Script नहीं: same requests। Important sense में brain नहीं: same model family, केवल Concept 9 वाला precision difference, जो numbers के साथ चलने वाला एक और variable है। Gap मुख्य रूप से serving layer का है। Practice जितना allow करती है, बाकी सब fixed रखा, एक चीज़ बदली और measured effect बहुत बड़ा है। यही honest claim है और पर्याप्त से अधिक strong है।
Friend chart देखकर कहता है: "तो vLLM model को fast बनाता है। Laptop पर भी use करना चाहिए।" Sentence में क्या सही और क्या गलत है? दोनों halves गलत हैं, और उससे lesson मिलता है। एक user के लिए vLLM model को fast नहीं बनाता: concurrency 1 पर curves अक्सर पास से शुरू होती हैं, क्योंकि single request card full रखने वाली techniques use नहीं कर सकती। vLLM load में machine को fast बनाता है, कई requests साथ serve करके। वह सामान्य laptop की मदद भी नहीं करता, क्योंकि continuous batching के लिए graphics card चाहिए। vLLM वहीं shine करता है जहाँ Ollama कभी जाने के लिए design नहीं हुआ: एक strong machine, कई users।Answer देखें
Concept 10 तब done है जब: chart मौजूद है, एक curve flat और एक climbing है, और एक sentence में बता सकते हैं कि gap मुख्य रूप से serving layer का क्यों है।
11. Coding agents को server से जोड़ें
Fast server तभी interesting है जब tools उसे use कर सकें। इसलिए Part 1 वाला move course के तीसरे address पर दोहराएँ: Claude Code और OpenCode को vLLM पर point करें।
अब यह लगभग suspicious लगना चाहिए: wiring वही है। vLLM दोनों agents के request formats बोलता है। OpenCode वाला OpenAI-style address और Claude Code का native Anthropic Messages format दोनों implement करता है, इसलिए बीच में translator नहीं है।
- Claude Code
- OpenCode
Part 1 वाली तीन settings, नया port और एक addition: Claude Code को बताएँ कि हर model tier served model पर map होता है।
export ANTHROPIC_BASE_URL=http://localhost:8000      # bare address again, no /v1
export ANTHROPIC_AUTH_TOKEN=dummy
export ANTHROPIC_API_KEY=dummy
export ANTHROPIC_DEFAULT_OPUS_MODEL=Qwen/Qwen3-8B
export ANTHROPIC_DEFAULT_SONNET_MODEL=Qwen/Qwen3-8B
export ANTHROPIC_DEFAULT_HAIKU_MODEL=Qwen/Qwen3-8B
claude
Model tier lines इसलिए हैं क्योंकि Claude Code आमतौर पर Anthropic के बड़े और छोटे models में name से switch करता है। तीनों tiers को served model पर map करने का अर्थ है कि वह जो भी माँगे, Qwen3 8B पाए। ये variables vLLM की Claude Code guide से आते हैं; drift होने पर वही live source check करें।
Part 1 का opencode.json copy करके दो strings बदलें: port और model name।
{
  "$schema": "https://opencode.ai/config.json",
  "provider": {
    "vllm": {
      "npm": "@ai-sdk/openai-compatible",
      "name": "vLLM (server)",
      "options": { "baseURL": "http://localhost:8000/v1" },
      "models": { "Qwen/Qwen3-8B": { "name": "Qwen3 8B (vLLM)" } }
    }
  },
  "model": "vllm/Qwen/Qwen3-8B"
}
ध्यान दें /v1 रहता है: OpenCode अब भी OpenAI style बोलता है और vLLM answer करता है। Part 1 का bare बनाम /v1 contrast बिना change के आ गया।
फिर throwaway folder में Concept 4 वाला exact task run करें:
इस folder को देखें। एक छोटा safe improvement खोजें, change करें और दिखाएँ कि क्या बदला।
Part 1 में laptop slow या broken था, तो यह payoff है। Same model, same task, लेकिन work के लिए बनी serving layer के पीछे real graphics card: Concept 5 की throughput wall चली गई और tool calls flow करती हैं, क्योंकि vLLM को tool-parser flags से start किया।
Sharing पर honest note। vLLM machine आपके अलावा किसी को serve करे, तो localhost machine का real address बनता है और internet पर open model server खुला door है। कम-से-कम vLLM को real secret वाली --api-key से start करें, users को key दें और machine को network की usual protections के पीछे रखें। vLLM docs safe serving cover करते हैं। Classroom use से पहले पढ़ें।
Concept 11 तब done है जब: कम-से-कम एक coding agent ने vLLM server से real task पूरा किया और Part 1 से बदली एक चीज़, address, तथा न बदली चीज़, बाकी सब, बता सकते हैं।
12. Server tier कब सही है
अब दोनों measured curves हैं, इसलिए decision fashionable के बजाय honest हो सकता है।
Server tier तब जीतता है जब एक strong machine कई mouths serve कर सके:
- Team या classroom। 50 laptops पर 50 students Part 1 की दोनों walls hit करते हैं। एक vLLM machine पर point किए 50 students एक cleared wall share करते हैं। Lab, company या PIAIC classroom एक GPU की price पर सबको capable agent ऐसे देता है।
- पूरा दिन चलने वाले loops। आगे Loop Engineering में बनाए agents हमेशा हर few minutes requests भेजेंगे। Per-token bill हमेशा बढ़ती है। अपनी GPU पहले से busy हो, तो एक और request लगभग कोई extra cost नहीं जोड़ती। Climbing curve कारण दिखाती है: load के साथ throughput बढ़ता है, इसलिए busy machine की per-token cost कम है।
- Team scale पर privacy। Part 1 का privacy argument पूरी organization के लिए: data आपके control की machine पर रहता है और सबको service मिलती है।
अब honest limit, जो Part 3 का bridge है। vLLM ने एक wall move की: throughput। दूसरी को नहीं छुआ। vLLM के पीछे Qwen3 8B 50 लोगों को जल्दी answer करता है और laptop जितना ही smart है, क्योंकि नीचे same brain है। Task 8B model के लिए hard हो, तो कोई serving layer नहीं बचा सकती। Capability wall बड़े brain से clear होती है और दुनिया के सबसे बड़े open brains rented machine या आपकी किसी future single machine में fit नहीं होते। उनके लिए address एक बार और बदलें।
पूरा दिन चलने वाला agent loop hard refactoring tasks पर wrong answers देता रहता है। Colleague उसे fix करने के लिए Ollama से vLLM पर जाने को कहता है। क्या वह काम करेगा? नहीं। Hard tasks पर wrong answers capability wall हैं और serving layer उसे नहीं छूती: vLLM same brain को fast serve करता है, smarter brain नहीं। vLLM पर जाने से queues और slowness, यानी throughput, fix होते हैं। Wrong answers fix करने के लिए strong model चाहिए, जिसके लिए Part 3 का cloud tier है। यह Concept 5 की table एक tier ऊपर है।Answer देखें
Concept 12 तब done है जब: ऐसी situation बता सकते हैं जहाँ server tier laptop और cloud दोनों से बेहतर है, और कह सकते हैं vLLM कौन-सी wall move करता और कौन-सी नहीं।
Part 3: Cloud tier। Frontier open models जिन्हें लगभग कोई self-host नहीं कर सकता (OpenRouter)
इस part की serving layer किसी और का cluster है, जिस तक OpenRouter से पहुँचते हैं। Scale ऐसे बड़े models हैं कि आपके और दुनिया की लगभग हर company के लिए "self-host" real option नहीं रहता।
13. ऐसे open weights जिन्हें उठा नहीं सकते: Kimi K3 और DeepSeek V4 Pro
Part 2 honest limit पर खत्म हुआ: capability wall बड़े brain से clear होती है। अब मौजूद सबसे बड़े open brains देखें और इस size पर "open" का अर्थ honestly समझें।
July 2026 में यह page लिखते समय course दो models use करता है, अलग reasons के लिए चुने गए:
- Kimi K3, Moonshot AI का, performance के लिए चुना। July 2026 में release हुआ 2.8 trillion parameter model, one million token context window के साथ। Release पर major capability indexes में अब तक का strongest open-weight model था, best closed models के पास। Rankings monthly बदलती हैं, इसलिए dated snapshot मानें और दोहराने से पहले current leaderboards check करें। Weights सच में open हैं। हर एक download कर सकते हैं।
- DeepSeek V4 Pro, DeepSeek का, price performance के लिए चुना। 1.6 trillion parameter model, लगभग 49 billion active per token, same one million token context window और MIT license के साथ। Raw capability में K3 से एक step नीचे और use में बहुत cheaper है; यही trade इसे यहाँ लाती है।
एक detail tiers को जोड़ती है: Moonshot ने K3 release करते समय उसकी नई attention design का serving code सीधे vLLM में contribute किया, ताकि hosts हर जगह चला सकें। Part 2 की industrial kitchen और इस part की frontier kitchens अक्सर अलग scales पर same software हैं।
अब honest arithmetic। "Open weights" का अर्थ है आप खुद run कर सकते हैं; यह नहीं कि आपके पास capability है। Moonshot K3 को 64 या अधिक accelerator chips की configurations पर one machine की तरह serve करने की सलाह देता है। DeepSeek V4 Pro छोटा model है, फिर भी self-host करने में 8 से 16 datacenter GPUs का cluster लगता है, hardware जिसकी cost house से अधिक है। Part 2 skills Qwen3 32B जैसे models या rented multi-GPU box पर 100B-class mixture तक scale होती हैं। यहाँ तक नहीं, और serious infrastructure teams के बाहर लगभग किसी की skills नहीं होतीं। Frontier open models सब rent करते हैं।
अगर rent ही करना है, तो "open" क्या देता है? तीन real चीज़ें। No lock-in: एक company model नहीं हटा सकती, अकेले reprice या silently change नहीं कर सकती, क्योंकि cluster वाला कोई भी same weights serve कर सकता है और competitors करते हैं। Landlord choice: कई companies same weights host करके price और speed पर compete करती हैं। Future floor: सच में matter करे, तो आप, देश या company hardware खड़ा कर सकते हैं। इस scale पर open weights का अर्थ "घर पर run करें" कम और "tap पर किसी एक का ownership नहीं" अधिक है।
Hosts की competition practical problem बनाती है: dozens hosting companies, सबके अपने accounts, keys और billing। OpenRouter इसे course के expected तरीके से solve करता है: एक address। Precise रहें, क्योंकि tier table simplify करती है। OpenRouter एक gateway है, router जो request receive करके असल model serve करने वाले host को forward करता है। Host serving layer operate करता है, अक्सर vLLM। OpenRouter front door operate करता है: hundreds models के लिए एक account, एक API key, एक billing page। openrouter.ai पर sign up, कुछ dollars credit, key create और सबसे पहले monthly spend limit set करें। Key एक string में secret और wallet है: commit या share होने वाले code में paste न करें।
Part 1 घर में cooking था। Part 2 अपनी industrial kitchen चलाना। Part 3 दुनिया के great restaurants हैं: 64 stoves और cooks की brigade वाली kitchens। आप घर में नहीं बनाएँगे और ज़रूरत भी नहीं। OpenRouter delivery app है जिसमें सभी restaurants एक menu पर, एक login और bill के साथ हैं। Phone app पूरे समय वही है।
Concept 13 तब done है जब: OpenRouter account, key और spend limit set है, और एक sentence में बता सकते हैं कि इस scale पर "open weights" व "आप self-host कर सकते हैं" same claim क्यों नहीं रहे।
14. उन्हीं दो agents से frontier brains चलाएँ
तीसरा tier, वही move। Parts 1 और 2 के exact harnesses को धरती के strongest open models पर point करेंगे और wiring लगभग शर्मनाक रूप से familiar लगेगी।
- Claude Code
- OpenCode
OpenRouter Claude Code का native format सीधे बोलता है, जिसे वह Anthropic-compatible endpoint कहता है। Setup Part 1 वाली तीन variables है, बीच में real key:
export ANTHROPIC_BASE_URL=https://openrouter.ai/api   # bare, one more time: no /v1
export ANTHROPIC_AUTH_TOKEN=sk-or-...                 # your OpenRouter key
export ANTHROPIC_API_KEY=                             # must be empty
claude --model moonshotai/kimi-k3
इसे कहीं persist करने से पहले hygiene note। Key wallet है। Shell exports एक session रहते हैं, शुरुआत की safe जगह। Variables settings file में ले जाएँ, तो home folder का ~/.claude/settings.json use करें, project की committed settings file कभी नहीं, क्योंकि git repository में pushed key strangers खर्च करेंगे।
OpenRouter model names maker/model shape follow करते हैं और exact string matter करती है: Kimi K3 के लिए moonshotai/kimi-k3, DeepSeek V4 Pro के लिए deepseek/deepseek-v4-pro। एक wrong character केवल "model not found" लौटाता है, इसलिए slugs type करने के बजाय openrouter.ai model page से copy करें।
Claude Code harness Anthropic के models के against build और test है, और OpenRouter full Claude Code compatibility केवल Anthropic first-party provider के साथ guarantee करता है। Kimi K3 और DeepSeek V4 Pro compatible format बोलते हैं और कई लोग उन्हें सफलतापूर्वक चलाते हैं, लेकिन tool call harness-model fit के कारण odd land कर सकती है, setup के कारण नहीं। Pairing को experimental मानें। Exercise का fully supported path चाहिए, तो OpenCode tab use करें: OpenRouter native OpenCode provider है, compatibility asterisk के बिना। Claude Code रखकर edges smooth करने हों, तो community ने इसी job का tool बनाया: Concept 16 में Claude Code Router।
दो habits एक evening बचाती हैं:
/statusसे verify करें कि words कहाँ जा रहे हैं।Anthropic base URLline पर OpenRouter address और token active credential दिखना चाहिए। Check पर भरोसा करें, assumption पर नहीं।- Claude Code current docs के अनुसार
ANTHROPIC_AUTH_TOKENsaved Anthropic login से पहले आता है, इसलिए past login requests hijack नहीं करना चाहिए। लेकिन stale login startup पर auth-conflict warning trigger कर सकता है और older guides interference report करती हैं।/statuswrong endpoint दिखाए या conflict warning दो credential sources बताए, तो/logoutएक बार run, restart और फिर check करें।
OpenCode OpenRouter को out of the box जानता है, इसलिए provider block नहीं लिखना। OpenCode के अंदर /connect run, OpenRouter select और key paste करें; older versions shell से opencode auth login use करते हैं। कई OpenRouter models preloaded हैं, इसलिए /models से चुन सकते या opencode.json में pin कर सकते हैं:
{
  "$schema": "https://opencode.ai/config.json",
  "model": "openrouter/deepseek/deepseek-v4-pro"
}
दूसरे को चलाने के लिए openrouter/moonshotai/kimi-k3 लगाएँ। बस यही पूरी configuration है।
अब same throwaway folder में Concept 4 task आख़िरी बार, दोनों models से एक-एक बार run करें:
इस folder को देखें। एक छोटा safe improvement खोजें, change करें और दिखाएँ कि क्या बदला।
पहले runs से difference महसूस करें। Queue, crawl या broken tool calls नहीं होने चाहिए: frontier models capability wall को बड़े margin से clear करते हैं और throughput wall किसी और के 64 stoves पर है। एक address बदलकर दोनों walls एक साथ clear। Run फिर भी stumble करे, तो cause भी move हुआ: local hardware नहीं, model-harness fit, provider, routing या prompt investigate करें।
जो छोड़ा उस पर भी ध्यान दें, क्योंकि trade lesson है। Concept 1 के बाद पहली बार words machine से बाहर गए और course में पहली बार tokens flow करते समय money cost करते हैं। Task के बाद OpenRouter activity page देखें और price वाली request दिखाई देगी। Private और free Part 1 थे। यह powerful और metered है।
Agent अब OpenRouter से tasks जल्दी complete करता है। Concept 1 की तुलना में छोड़ी दो चीज़ें और words का destination सच बताने वाली एक habit बताएँ। आपने privacy छोड़ी, क्योंकि words machine से निकलकर provider से जाते हैं, और free छोड़ा, क्योंकि हर token credit से meter होता है। Habit check करना है, assume नहीं: Claude Code में Answer देखें
/status या OpenCode model picker exact address दिखाता है। Part 1 का rule हर tier पर है: visible setting पर भरोसा करें, याद वाले setup पर नहीं।
Concept 14 तब done है जब: K3 और V4 Pro दोनों ने agent से real coding task complete किया, /status या OpenCode model picker requests का destination confirm करता है और activity page पर real price वाली real request देखी है।
15. Performance या price: model और tier चुनना
आपने दोनों frontier models चलाए। उनकी cost same नहीं और choice वह decision है जो अब लगातार लेंगे।
यह page लिखते समय list prices लगभग: Kimi K3 के लिए $3 per million input tokens और $15 per million output tokens, DeepSeek V4 Pro के लिए लगभग $0.44 input और $0.87 output। Gap धीरे पढ़ें: output में price-performance choice performance choice से लगभग 17 गुना cheaper है। Prices तेज़ी से बदलती हैं, इसलिए numbers को version number की तरह मानें: reasoning का snapshot, और budget से पहले models के OpenRouter pages पर live check।
तो K3 17 गुना अधिक कब सही है? जब task इतनी hard हो कि V4 Pro fail करे और failure की cost आपका time हो। एक successful लंबा agentic run उन पाँच cheap runs से बेहतर है जिन्हें सुलझाना पड़े। Teams का working rule: price-performance model default रखें, cheap model insufficient prove होने पर performance model तक escalate करें, और vibes नहीं, real failures escalation trigger करें। Agents के लिए एक number पूरी calculation बदलता है: cached input। Agent हर turn same instructions और repository context फिर भेजता है, और repeated prefix cache hit करे तो दोनों providers input price का tiny fraction charge करते हैं। Loop-style workloads में effective bill अक्सर list-price math से बहुत कम होती है। Pricing pages हर provider के caching rules समझाती हैं। Agent work में वह section पहले पढ़ें, आख़िर में नहीं।
अब पूरा zoom out करें, क्योंकि full picture earned है। एक harness, एक idea, तीन tiers:
| Tier | Serving layer | इस course का brain | Address | Compute कौन pay करता है | किसमें जीतता है |
|---|---|---|---|---|---|
| Local | Ollama | Qwen3 8B | आपका localhost | पहले pay कर चुके (laptop) | privacy, offline, free, learning |
| Server | vLLM | Qwen3 8B, serving-specific build | आपके control की machine | आप, GPU hour के हिसाब से | कई users, all-day loops, team data |
| Cloud | OpenRouter (gateway) | Kimi K3, DeepSeek V4 Pro | openrouter.ai | आप, per token | hardest tasks, zero setup, frontier |
Decision procedure, questions के order में। पहला, क्या data बाहर जा सकता है? नहीं, तो cloud tier बाहर; कितने लोगों को service चाहिए उसके अनुसार local या server चुनें। दूसरा, क्या task mid-size open model की reach में है? हाँ, तो tier economics है: एक के लिए laptop, कई या loops के लिए vLLM machine। तीसरा, task को frontier brain चाहिए, तो cloud tier और concept का rule: cheap model default, proven failure पर expensive। तीन questions में open-model deployment की हर conversation fit होती है।
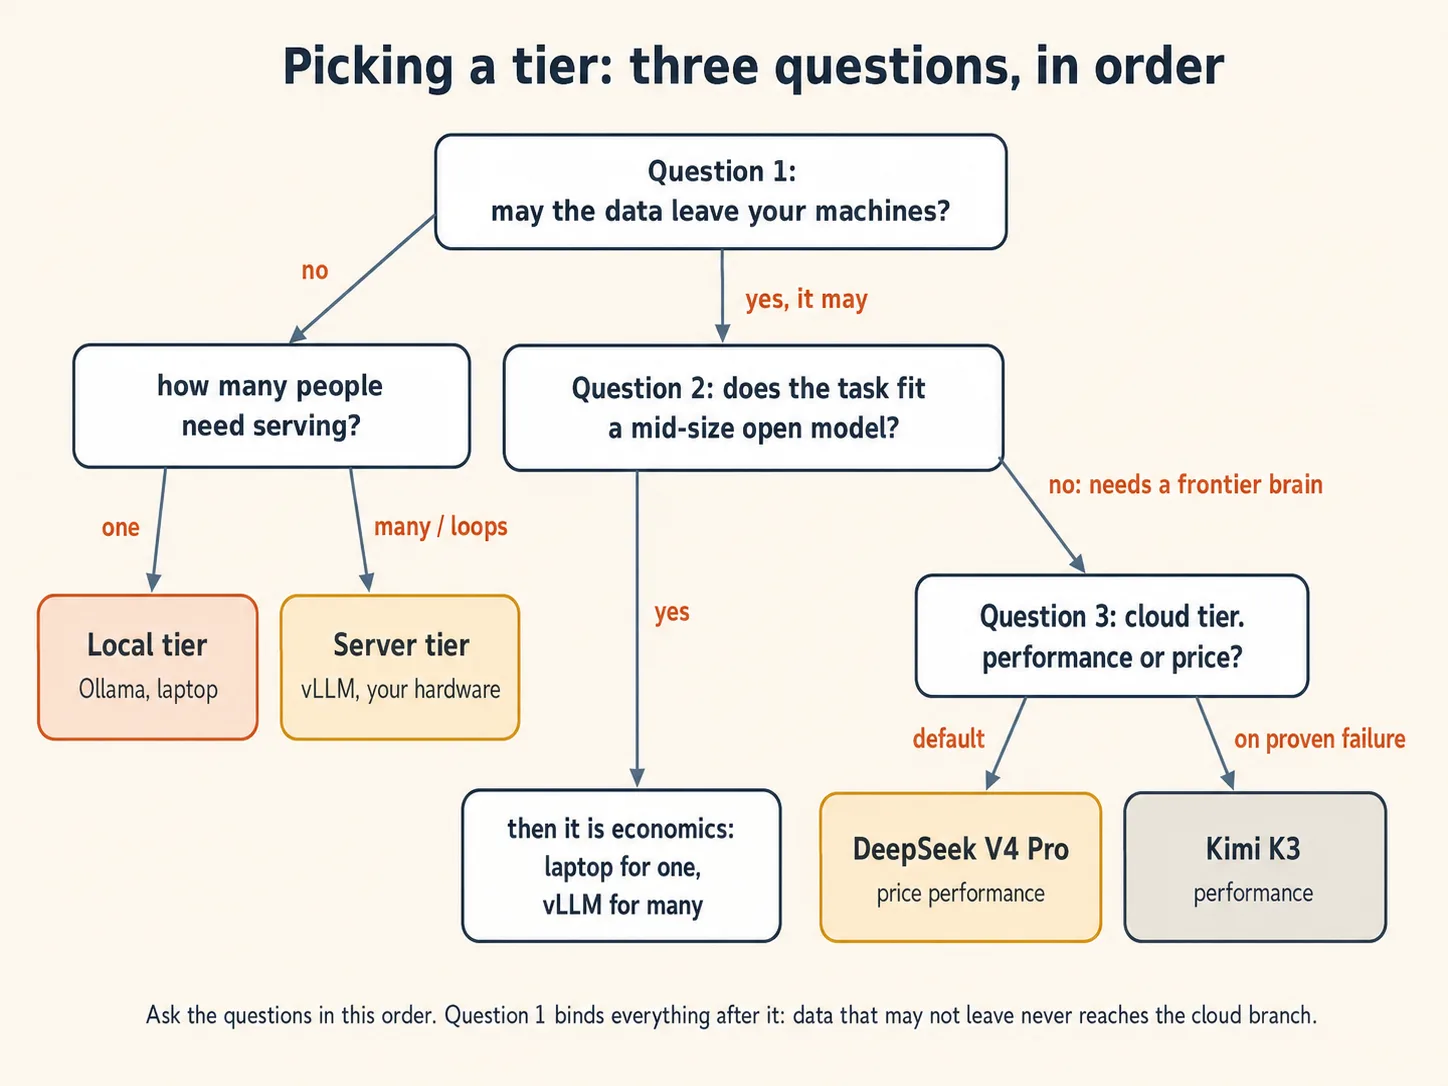
Firm को agent चाहिए जो confidential client contracts हर दिन पूरा दिन review करे। Tasks moderately hard हैं, लेकिन strong mid-size model की reach में हैं। कौन-सा tier और बाकी दोनों गलत क्यों? Server tier। Question one cloud हटाता है: confidential contracts firm के control वाली machines से बाहर नहीं जाने चाहिए। Laptop tier दो reasons से fail: कितने people serve करने हैं और दिन में कितनी देर run करना है। Team के लिए all-day loop तुरंत throughput wall hit करता है। Firm network के अंदर vLLM machine throughput clear करती, data घर रखती और all-day loop को per token cheap बनाती है। Tasks model के लिए hard prove हों, तो real choice bigger rented box पर बड़ा open model है, public cloud नहीं, क्योंकि question one अब भी bind करता है।Answer देखें
Concept 15 तब done है जब: तीन questions order में बता सकते हैं और उस scenario के tier choice को defend कर सकते हैं जिसका answer किसी ने नहीं दिया।
16. तीनों tiers के लिए एक router: Claude Code Router
इस course की नींव एक idea थी: brain केवल address है। Natural last step है और popular community tool उसे करता है। क्या होगा अगर address एक brain नहीं, decision की ओर point करे?
Claude Code Router (CCR) musistudio का open source tool और Claude Code ecosystem के सबसे-starred projects में एक है। वह machine पर छोटा server चलाता है, एक ओर Claude Code का native format और दूसरी ओर कई providers से बात करके बीच में translate करता है। Claude Code को एक बार point करें, फिर config file हर request पर तय करती है कौन-सा brain answer दे। Course के आखिर में इसे जानने के तीन reasons हैं:
- Task type से route करता है।
Routerblock Claude Code के अलग work को models पर map करता है: ordinary work के लिएdefault, cheap housekeeping के लिएbackground, hard reasoning के लिएthink, token threshold पार requests के लिएlongContext। List फिर धीरे पढ़ें। यह Concept 15 का rule है, price-performance default और hard cases में escalation, discipline के बजाय config में। - सीखे हर tier तक जाता है। Config में provider केवल name, address और model list है। इसलिए एक file Ollama laptop, vLLM server और OpenRouter को साथ रखकर route कर सकती है।
- Rough edges smooth करता है। Transformers (
openrouter,tooluse,enhancetoolऔर दूसरे) provider के अनुसार requests व responses adapt करते हैं, loosely formatted tool calls में error tolerance भी जोड़ते हैं। यह Concept 14 की compatibility caution का community working answer है।
तीन steps में setup करें। Claude Code के पास install करें:
npm install -g @musistudio/claude-code-router
फिर ~/.claude-code-router/config.json बनाएँ। यह config पूरे course के तीनों tiers एक address के पीछे रखती है:
{
  "OPENROUTER_API_KEY": "$OPENROUTER_API_KEY",
  "Providers": [
    {
      "name": "ollama",
      "api_base_url": "http://localhost:11434/v1/chat/completions",
      "api_key": "ollama",
      "models": ["qwen3:8b"]
    },
    {
      "name": "vllm",
      "api_base_url": "http://localhost:8000/v1/chat/completions",
      "api_key": "dummy",
      "models": ["Qwen/Qwen3-8B"]
    },
    {
      "name": "openrouter",
      "api_base_url": "https://openrouter.ai/api/v1/chat/completions",
      "api_key": "$OPENROUTER_API_KEY",
      "models": ["deepseek/deepseek-v4-pro", "moonshotai/kimi-k3"],
      "transformer": { "use": ["openrouter"] }
    }
  ],
  "Router": {
    "default": "openrouter,deepseek/deepseek-v4-pro",
    "background": "ollama,qwen3:8b",
    "think": "openrouter,moonshotai/kimi-k3",
    "longContext": "openrouter,moonshotai/kimi-k3",
    "longContextThreshold": 60000
  }
}
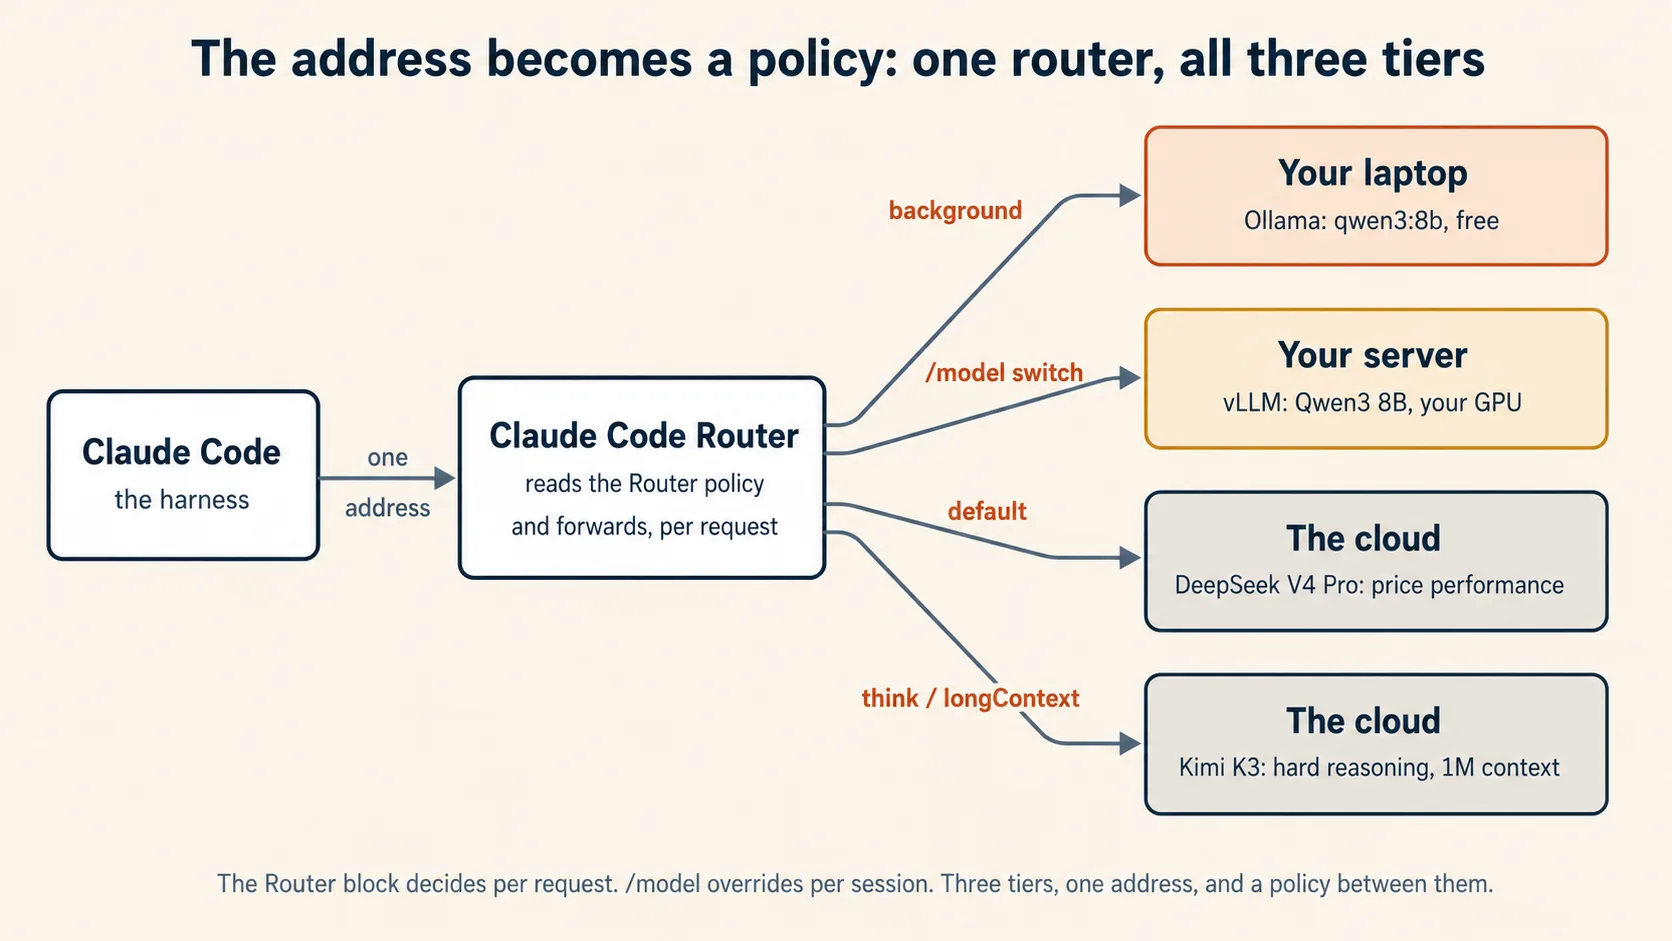
Router block को policy की तरह पढ़ें, क्योंकि वही है। Ordinary work price-performance frontier model पर जाता है। Cheap background chores laptop पर free रहते हैं। Hard reasoning और huge contexts Kimi K3 पर escalate होते हैं, जिसकी one million token window longContext slot earn करती है। $OPENROUTER_API_KEY syntax environment से key लेती है, इसलिए secret file में नहीं बैठता।
फिर router के ज़रिए Claude Code start करें:
ccr code
कुछ mechanics समय बचाते हैं: config edit के बाद changes apply करने के लिए ccr restart run करें। Claude Code के अंदर /model provider,model से session के बीच brains switch करें, जैसे /model ollama,qwen3:8b। JSON की जगह web page में config edit करना पसंद हो, तो ccr ui खोलता है।
आख़िर में दो honest notes। पहला, CCR community project है, Anthropic या provider का product नहीं। तेज़ी से बदलता है, transformers guarantees नहीं working fixes हैं और हर request अब एक और software से जाती है जिसे update और release notes पढ़ना चाहिए। दूसरा, जहाँ ज़रूरत नहीं वहाँ न जोड़ें। Part 2 vLLM server Claude Code format native बोलता है, इसलिए केवल उसके आगे router कुछ नहीं देता। CCR तब सही है जब एक Claude Code को कई brains पर एक साथ task के अनुसार route करना हो। Course के बाद यही setup समझते हैं: तीन tiers, एक address और उनके बीच policy।
Concept 16 तब done है जब: Claude Code router से run करता है, one session में कम-से-कम दो tiers answer करते हैं (/model provider,model से switch करके source देखें), और अपने Router block को encoded tier policy की तरह पढ़ सकते हैं।
आज अपने scale पर try करें, फिर आगे बढ़ें
आज सबसे छोटा real version करें। Ollama install, model run और chat करें: केवल इतना दो minutes में private on-machine AI देता है। Code लिखते हैं, तो coding agent connect करके hit होने वाली wall महसूस करें। Afternoon के लिए GPU rent कर सकें, तो 50-request experiment और अपनी curves बनाएँ: किताब में कम exercises एक hour में अधिक सिखाती हैं। Task हर host हो सकने वाले brain को हरा दे, तो आख़िरी बार address बदलकर cents या dollars में frontier brain borrow करें। दूसरे लोगों को बनाया work चाहिए, तो Appendix A server को shared service बनाता है।
Mental model आगे रखें, क्योंकि section order में इसी पर बनता है। Tool harness और swappable brain है, और brain केवल address। Address laptop, server या दुनिया के biggest open models पर point कर सकता है, harness difference नहीं जानता। दो walls setup की सीमा तय करती हैं: serving layer और hardware throughput move करते हैं, केवल बड़ा brain capability। अब Agentic Coding में agent चलाना, Spec-Driven Development में written spec से direct करना और Loop Engineering में all-day unattended loop देना सीखेंगे। Last course तक जानेंगे किसका brain कौन-से tier पर loop चलाए और keep-running cost क्या है।
One-line summary
Open source models तीन scales पर run होते हैं और tool एक address के ज़रिए तीनों तक पहुँचता है। एक person के लिए Ollama, कई के लिए vLLM, लगभग किसी के self-host न कर सकने वाले frontier brains के लिए OpenRouter। अपनी दो curves से difference एक बार measure करें और career भर सही tier चुनेंगे।
Appendix A: Mini LLM cloud बनाएँ
Part 2 ने आपको industrial kitchen दी। Kitchen restaurant नहीं होती। यह appendix front door, menu, table numbers और bill जोड़ता है, ताकि एक person को अच्छी तरह serve करने वाली machine पूरी class को safely serve कर सके।
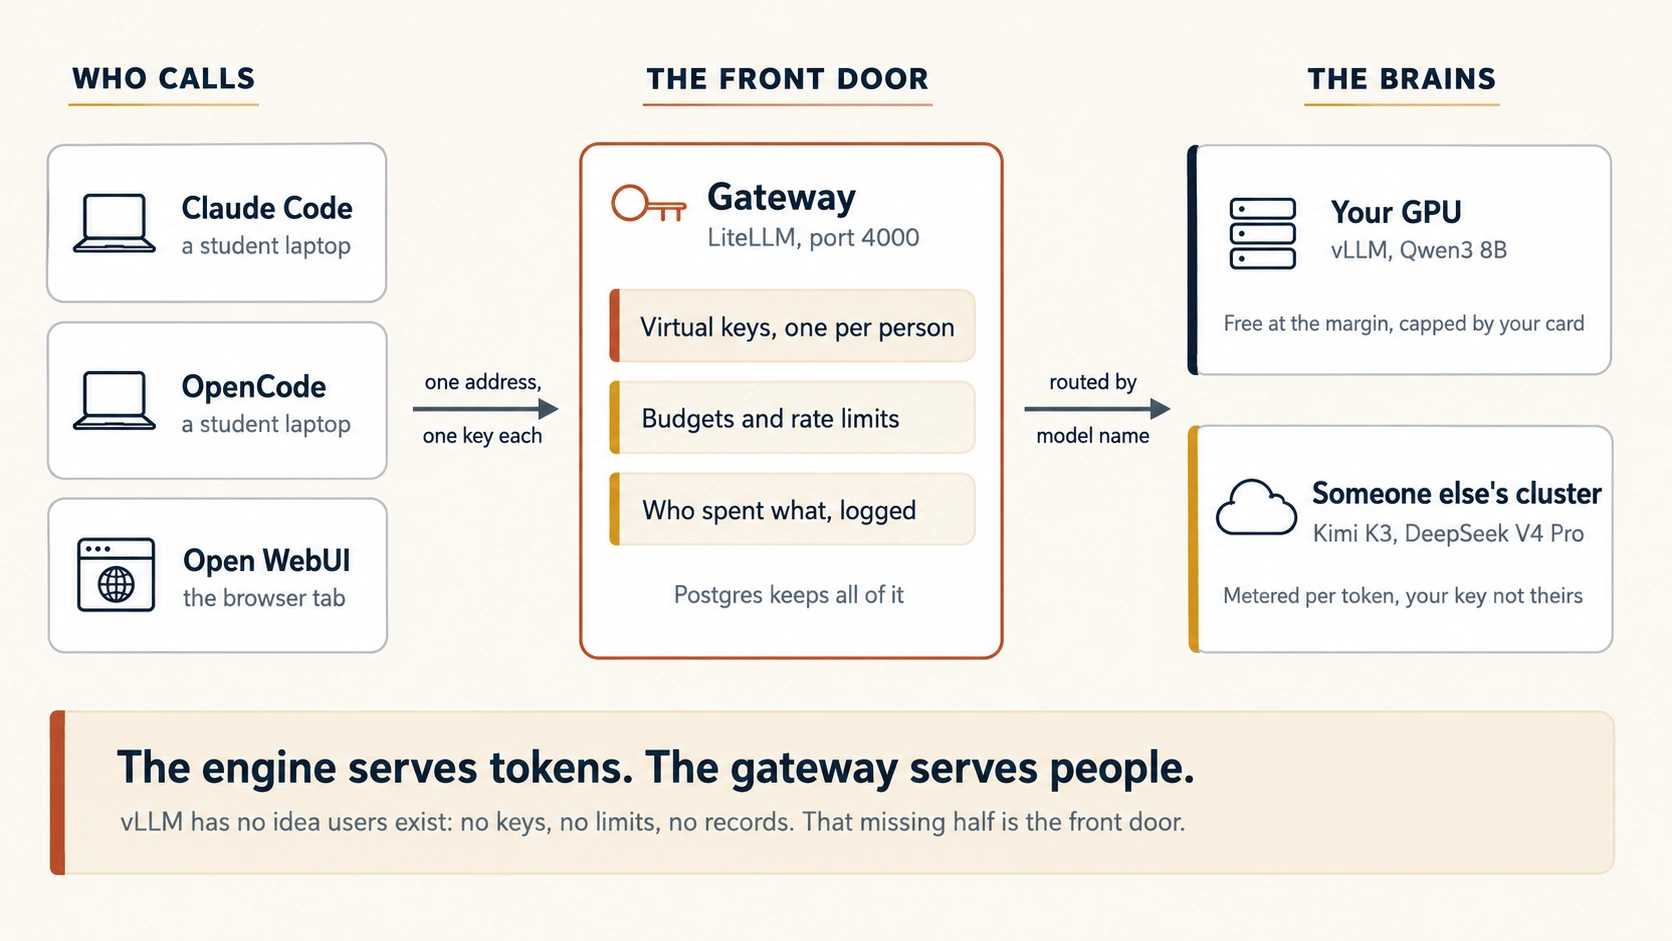
यह appendix जिस gap को close करता है, वह यह है। Part 2 के अंत में vLLM Qwen3 8B serve कर रहा था और आपकी fifty-request curve वहाँ चढ़ रही थी जहाँ Ollama की flat हो गई थी। यह real achievement है, लेकिन अभी service नहीं है। इसे class को देने की कोशिश करें तो questions तुरंत शुरू होते हैं। इसे use करने की permission किसे है? एक student के runaway loop को पूरी machine एक week तक खा जाने से क्या रोकता है? किसने कितना spend किया? जब Qwen3 8B काफ़ी न हो, तो student frontier brain तक कैसे पहुँचे, बिना आपकी अपनी OpenRouter key दो सौ लोगों को दिए?
इनमें से कोई question tokens serve करने के बारे में नहीं है, और ठीक इसी कारण vLLM उनका answer नहीं देता। Inference engine model load करके requests का answer देता है। उसे users के होने का पता नहीं। उसके पास keys, quotas, spending records या मना करने का तरीका नहीं। उस missing half का एक नाम है, और उसे बनाना ही इस appendix का विषय है।
Course का एक idea यहाँ तक चलता है। Brain केवल address है। Part 1 में address आपका laptop था। Part 2 में वह आपकी control की machine थी। Part 3 में किसी और का cluster था। इस appendix में आप address बनते हैं: वह चीज़ बनाते हैं जिसकी ओर दूसरे लोग अपने agents point करते हैं।
Part 2 की हर चीज़, साथ में उसी GPU machine पर Docker और Docker Compose। Part 3 किया है, तो Concept A5 के लिए अपनी OpenRouter key पास रखें। बिना कुछ run किए पूरा appendix पढ़ सकते हैं, और stack कभी न बनाएँ तब भी Concepts A1, A2 और A7 पढ़ना उपयोगी है।
एक नहीं, दो programs। vLLM tokens serve करता है। उसके आगे gateway बैठता है और वह सब handle करता है जो vLLM नहीं करता: user keys, spending limits, model routing और logs। यहाँ use किया gateway LiteLLM है। Postgres जोड़ें ताकि restart के बाद keys और spending बनी रहें, और Open WebUI जोड़ें ताकि terminal use न करने वाले लोग भी आपका cloud use कर सकें। Four containers, one file, one afternoon।
इस appendix के नए words
| Term | आसान meaning |
|---|---|
| Inference engine | वह program जो model load करके requests के answer देता है। vLLM एक inference engine है। यह tokens जानता है, लोगों को नहीं। |
| Gateway / proxy | Engine के आगे वाला program। यह लोगों के बारे में जानता है: कौन call कर रहा है, क्या use कर सकता है और cost क्या है। |
| Virtual key | Per-person API key जो आपका gateway issue और revoke करता है, और जिसके अपने limits होते हैं। |
| Budget | Key की spending cap। इसके ख़त्म होने पर gateway bill बढ़ाने की जगह request refuse कर देता है। |
| Rate limit | Requests per minute की cap, ताकि एक busy user बाकी सबको बाहर न कर दे। |
| Multi-tenancy | Shared hardware से कई अलग users को serve करना, बिना उन्हें एक-दूसरे को affect करने दिए। |
| Fallback | Rule जो कहता है, "अगर यह model fail या full हो, तो उसकी जगह वह वाला try करें।" |
A1. Kitchen restaurant नहीं होती
Concept 8 से course जिस metaphor को use करता आया है, उसे एक step आगे ले जाएँ। Ollama दो burners वाली home kitchen थी। vLLM industrial kitchen थी जो हर burner को जलता रखती है। ये दोनों घर का back हैं।
Restaurant को front of house भी चाहिए। Door पर कोई जो जाने कि reservation है या नहीं। Menu जो बताए कि आज क्या available है। Table number, ताकि kitchen को पता हो हर dish कहाँ जाती है। अंत में bill। इनमें से कुछ भी cooking नहीं है, और बिना front of house की शानदार kitchen restaurant नहीं होती। वह kitchen है जिसमें strangers भटककर अंदर आ जाते हैं।
Bare vLLM server की हालत ठीक यही है। Port तक पहुँचने वाला कोई भी person इसे free में हमेशा use कर सकता है। यह क्या नहीं करता, उसे धीरे पढ़ना उपयोगी है, क्योंकि हर item वह चीज़ है जो वरना आपको ख़ुद बनानी पड़ेगी:
| आपको क्या चाहिए | क्या vLLM यह करता है? |
|---|---|
| एक साथ कई users को तेज़ी से tokens serve करना | हाँ। यही इसका पूरा काम है और यह इसमें excellent है। |
| यह जानना कि कौन call कर रहा है | नहीं। |
| Spending limit पर किसी को रोक देना | नहीं। |
| एक user को बाकी सबको बाहर करने से रोकना | कुछ हद तक queueing से, लेकिन per user नहीं। |
| एक address पर एक से अधिक model offer करना | नहीं। One server, one model। |
| इसके fail होने पर दूसरे model पर fallback करना | नहीं। |
| किसने कितना spend किया, record करना | नहीं। |
| Local model fail होने पर cloud model तक पहुँचना | नहीं। |
उस table का हर "नहीं" gateway का काम है।
Kitchen खाना बनाती है। Front of house तय करता है कौन खाए, menu में क्या है और pay कौन करे। आपने बहुत अच्छी kitchen बनाई है। अब आपको door चाहिए।
इस point पर fair question है: क्या कोई एक program दोनों करता है? लगभग, और honest answer मायने रखता है। Serving infrastructure problem है, और open source world ने इसे बहुत अच्छी तरह solve किया है। Metering, quotas और billing product problem है, और inference companies असल में यही बेचती हैं। इसलिए open tools engine और meter अलग pieces में देते हैं, और आप उन्हें assemble करते हैं। अच्छी बात यह है कि यहाँ हर layer वही OpenAI-compatible request shape बोलती है जिसे Part 1 से use कर रहे हैं, इसलिए assembly का मतलब configuration है, translation work नहीं।
Concept A1 तब done है जब: bare vLLM server की तीन ऐसी चीज़ें बता सकें जिनकी fifty students की class को day one पर ज़रूरत होगी।
A2. Gateway: एक address, कई brains, real users
Gateway एक छोटा program है जो एक या अधिक model servers के आगे बैठता है। Requests gateway पर आती हैं, gateway तय करता है उनके साथ क्या करना है और फिर उन्हें आगे भेजता है। यह front door है।
आप एक पहले ही use कर चुके हैं। Part 3 का OpenRouter gateway है: एक address, एक key, एक bill, उसके पीछे hundreds of models और actual serving ऐसे hosts करते हैं जिन्हें आप direct contact नहीं करते। यह appendix वही shape अपने scale पर, अपनी machine पर बनाता है, जहाँ company की जगह operator आप हैं।
इस काम के लिए यहाँ LiteLLM है, एक open source proxy जो users से OpenAI-compatible shape में बात करता है और बाहर providers की लंबी list के लिए translate करता है, जिसमें आपका अपना vLLM server भी है। चार चीज़ें इसे सही piece बनाती हैं:
- Virtual keys। हर student को अपनी key issue करते हैं। उस पर limits लगा सकते हैं, उसका spend देख सकते हैं और semester ख़त्म होने या laptop खोने पर तुरंत revoke कर सकते हैं।
- Budgets और rate limits। Key में spending cap और per-minute limit हो सकती है। Runaway loop cap hit करे, तो gateway अगली request refuse कर देता है। आपका bill उस number पर बढ़ना रोक देता है जिसे पहले चुना था।
- एक address पर models का menu। आपका local Qwen3 8B और frontier cloud model दोनों एक ही gateway पर दिख सकते हैं, और वही students उसी key से दोनों तक पहुँच सकते हैं।
- Records। हर request user के against log होती है, इसलिए "किसने कितना spend किया" investigation नहीं, query है।
इसका shape notice करें। Gateway किसी चीज़ को faster नहीं बनाता। यह tokens per second के बारे में कुछ नहीं बदलता और अपने कुछ milliseconds जोड़ता है। यह performance tool बिल्कुल नहीं। यह control tool है, और control ही server को service में बदलता है।
Student कहता है gateway बेकार है क्योंकि "vLLM मुझे पहले ही OpenAI-compatible address देता है, इसलिए मैं वही use कर सकता हूँ।" सबसे strong reply क्या है? Address के बारे में वे सही और service के बारे में ग़लत हैं। vLLM address एक trusted person के लिए ठीक काम करता है, और इसी कारण Concept 11 वहाँ रुक सकता था। Gateway उस हर चीज़ के लिए है जो कई लोगों के आते ही सामने आती है: separate keys, spending caps, rate limits, एक से अधिक models का menu, fallbacks और किसने क्या use किया उसका record। इनमें से कोई speed feature नहीं है, इसलिए comparison उस day तक ख़ाली लगता है जब runaway loop पूरे weekend चलता रहे और कोई न बता सके कि वह किसका था।Answer देखें
Concept A2 तब done है जब: एक sentence में बता सकें कि gateway क्या जोड़ता है जो inference engine कभी नहीं देगा, और यह speed feature क्यों नहीं है।
A3. इसे खड़ा करें: पूरा stack एक file में
Four containers। One machine। One file।
| Container | काम |
|---|---|
| vllm | आपके GPU पर Qwen3 8B serve करता है। Concept 9 वाला ही server, अब उसके आगे door है। |
| litellm | Gateway। यही एक चीज़ है जिसे आपके users कभी touch करते हैं। |
| postgres | Keys, users, budgets और spending store करता है, ताकि restart आपकी class को wipe न करे। |
| open-webui | आपकी class में terminal use न करने वाले लोगों के लिए chat page। |
Gateway की अपनी config से शुरू करें। इसे litellm-config.yaml के रूप में save करें:
model_list:
  # Your own GPU, from Part 2. Students see the name on the left.
  - model_name: qwen3-8b
    litellm_params:
      model: hosted_vllm/Qwen/Qwen3-8B
      api_base: http://vllm:8000/v1
      api_key: "not-needed"

general_settings:
  master_key: os.environ/LITELLM_MASTER_KEY
  database_url: os.environ/DATABASE_URL

litellm_settings:
  drop_params: true
वहाँ दो details के नाम जानना उपयोगी है। model_name वह नाम है जो आपके users type करते हैं, और उसका नीचे वाले real model name से match करना ज़रूरी नहीं: यही indirection आपको बाद में बिना किसी को बताए brain swap करने देता है। और master_key पूरे cloud का आपका admin password है। यह student key नहीं। यह आपकी machine से कभी बाहर नहीं जाता।
अब stack। इसे docker-compose.yml के रूप में save करें:
services:
  vllm:
    image: vllm/vllm-openai:latest
    command: >
      --model Qwen/Qwen3-8B
      --enable-auto-tool-choice
      --tool-call-parser hermes
      --reasoning-parser qwen3
    volumes:
      - ./hf-cache:/root/.cache/huggingface
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: all
              capabilities: [gpu]

  postgres:
    image: postgres:16
    environment:
      POSTGRES_DB: litellm
      POSTGRES_USER: litellm
      POSTGRES_PASSWORD: ${POSTGRES_PASSWORD}
    volumes:
      - ./pgdata:/var/lib/postgresql/data

  litellm:
    # Pin the version. Read the security note below before you change this.
    image: ghcr.io/berriai/litellm:main-v1.80.5
    depends_on: [vllm, postgres]
    ports:
      - "4000:4000"
    environment:
      LITELLM_MASTER_KEY: ${LITELLM_MASTER_KEY}
      DATABASE_URL: postgresql://litellm:${POSTGRES_PASSWORD}@postgres:5432/litellm
    volumes:
      - ./litellm-config.yaml:/app/config.yaml
    command: ["--config", "/app/config.yaml", "--port", "4000"]

  open-webui:
    image: ghcr.io/open-webui/open-webui:main
    depends_on: [litellm]
    ports:
      - "3000:8080"
    environment:
      OPENAI_API_BASE_URL: http://litellm:4000/v1
      OPENAI_API_KEY: ${LITELLM_MASTER_KEY}
    volumes:
      - ./webui-data:/app/backend/data
अपनी दो secrets इसके पास .env file में रखें, compose file में कभी नहीं:
LITELLM_MASTER_KEY=sk-choose-a-long-random-string
POSTGRES_PASSWORD=choose-another-long-random-string
फिर इसे up करके साबित करें कि यह काम करता है:
docker compose up -d

curl http://localhost:4000/v1/chat/completions \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model": "qwen3-8b", "messages": [{"role": "user", "content": "Say hello in one line."}]}'
उस request को Concept 9 वाली request के पास देखें। Same shape, same /v1/chat/completions, एक नई line: Authorization header। यही single header server और service के बीच पूरा difference है। अब किसी को बताना पड़ता है कि वह कौन है।
March 2026 में LiteLLM package supply chain attack का target बना और malicious releases हटाए जाने से पहले बाहर चली गईं। आपका gateway cloud की हर key और हर spending record रखता है, इसलिए यह stack का highest-value target है। इसलिए exact version tag pin करें, latest कभी track न करें, move करने से पहले release notes पढ़ें और दोनों काम करने तक gateway को public internet से दूर रखें। यह LiteLLM-specific warning नहीं है। Credentials रखने वाली कोई भी service run करने का यही मतलब है।
Driver और CUDA mismatches आम cause हैं, और इसी कारण compose file pip install की जगह official image use करती है। Host पर NVIDIA Container Toolkit भी installed चाहिए, वरना Docker के अंदर GPU दिखाई नहीं देगा। 16 GB card है, तो Concept 9 की तरह model line को Qwen/Qwen3-8B-FP8 से swap करें।
Concept A3 तब done है जब: docker compose up -d four containers को up करे, port 4000 से curl answer लौटाए और Authorization header के बिना वही request refuse हो।
A4. Keys बाँटें: budgets, limits और किसने कितना spend किया
यही concept इसे cloud बनाता है। इससे पहले की हर चीज़ plumbing थी।
एक student के लिए key generate करें:
curl -X POST http://localhost:4000/key/generate \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "user_id": "student-0417",
    "models": ["qwen3-8b"],
    "max_budget": 2.00,
    "budget_duration": "30d",
    "rpm_limit": 20
  }'
चारों settings पढ़ें, क्योंकि हर एक decision है जो आप जानबूझकर ले रहे हैं:
user_idहर future request और हर logged dollar को एक person से जोड़ता है। इसके बिना usage report एक बड़ा anonymous number है।modelsवह menu है जिससे यह key order कर सकती है। केवलqwen3-8blist करने वाली key किसी और चीज़ तक नहीं पहुँच सकती, चाहे student कुछ भी type करे।max_budgetके साथbudget_durationcap है। Two dollars a month, फिर gateway refuse करना शुरू करता है। Runaway loop रात में, आपको जगाए बिना, अपने आप रुक जाता है।rpm_limitएक enthusiastic student को बाकी सबके लिए queue भरने से रोकता है।
Response ऐसी key के साथ लौटता है जो sk- से शुरू होती है। Student को केवल वही string मिलती है। और कुछ नहीं।
अब वह moment जिसके लिए यह पूरा appendix है। Student आपका cloud ठीक उसी तरह use करता है जैसे Part 3 ने OpenRouter use किया था। वही two settings, नया address:
# OpenCode, or anything speaking the OpenAI shape
export OPENAI_BASE_URL="http://your-server:4000/v1"
export OPENAI_API_KEY="sk-the-students-key"
Harness को कभी पता नहीं चलता कि कुछ बदला है। यह अब भी harness plus brain plus address है, और अब address आपकी अपनी building की एक machine है।
ख़ास तौर पर Claude Code के लिए LiteLLM Anthropic-format endpoint भी expose करता है, जिससे ANTHROPIC_BASE_URL को direct अपने gateway पर point कर सकते हैं, वही bare-address move जो तीन बार पहले कर चुके हैं। वह surface इस page के track कर सकने से faster move करता है, इसलिए उस पर निर्भर होने से पहले live LiteLLM docs check करें। Pinned version पर यह काम न करे, तो Concept 16 का Claude Code Router एक extra hop से वहाँ पहुँचा देता है और gateway उसकी config में केवल एक और provider बन जाता है।
Class live होने के बाद ये two commands लगातार use करेंगे:
# What has this key spent?
curl -X GET "http://localhost:4000/key/info?key=sk-the-students-key" \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY"

# Semester over, or laptop lost.
curl -X POST http://localhost:4000/key/delete \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY" \
  -H "Content-Type: application/json" \
  -d '{"keys": ["sk-the-students-key"]}'
हर diner को spending limit के साथ अपना table number मिलता है। Kitchen बिल्कुल नहीं बदली। लेकिन अब जानते हैं कौन खा रहा है, एक table को पूरा menu order करने से रोक सकते हैं और किसी के जाने पर उसकी table वापस ले सकते हैं।
आप two hundred student keys issue करते हैं, हर एक पर two dollars a month की cap है और सभी आपके अपने GPU की ओर point करती हैं। Colleague पूछता है local model की per token कोई cost नहीं, तो budgets की परेशानी क्यों ली। Real answer क्या है? Two answers हैं और दूसरा important है। पहला, local में भी "free" ग़लत है: आपके GPU की fixed throughput है, ठीक जैसा Part 2 की curve ने card भरने पर दिखाया था, इसलिए money move न होने पर भी एक student का endless loop बाकी सबकी capacity spend कर रहा है। Budget shared resource को ration करता है। दूसरा, और Concept A5 यहीं जाता है, menu में cloud model जोड़ते ही उन्हीं keys से real money flow होता है। Free रहते हुए budget habit set करने का मतलब है कि free होना बंद होने वाले day panic में इसे नहीं बना रहे।Answer देखें
Concept A4 तब done है जब: अलग machine पर दूसरे person ने अपनी key से आपके gateway के through real task run किया, आपने देखा कि उसने कितना spend किया और बाद में key revoke कर दी।
A5. तीनों tiers एक door के पीछे रखें
आपका cloud अभी one brain offer करता है। अब course के दूसरे two tiers को उसी menu में जोड़ें, ताकि student model name बदलकर tier चुने और कुछ नहीं।
litellm-config.yaml extend करें:
model_list:
  # Tier 2: your own GPU. Free at the margin, capped by your hardware.
  - model_name: qwen3-8b
    litellm_params:
      model: hosted_vllm/Qwen/Qwen3-8B
      api_base: http://vllm:8000/v1
      api_key: "not-needed"

  # Tier 3: a frontier brain, rented. Your key, never theirs.
  - model_name: frontier
    litellm_params:
      model: openrouter/moonshotai/kimi-k3
      api_key: os.environ/OPENROUTER_API_KEY

  # Tier 3, the cheap end. The right default for high-volume work.
  - model_name: frontier-cheap
    litellm_params:
      model: openrouter/deepseek/deepseek-v4-pro
      api_key: os.environ/OPENROUTER_API_KEY

router_settings:
  fallbacks:
    - qwen3-8b: ["frontier-cheap"]
अभी three things हुईं और हर एक अपना sentence deserve करती है।
आपकी OpenRouter key machine से कभी बाहर नहीं जाती। Two hundred students अब Kimi K3 तक पहुँच सकते हैं और उनमें से किसी के पास ऐसा credential नहीं जो public repository में paste हो सके। उनके पास आपकी gateway key है, जिसे one command में revoke कर सकते हैं और जो अपनी cap से आगे spend नहीं कर सकती। Concept 14 ने warn किया था कि OpenRouter key एक string में secret और wallet दोनों है। String दिए बिना wallet share करने का यही तरीका है।
Tier choice model name बन गई। Hard refactor के लिए frontier brain चाहने वाला student frontier type करता है, qwen3-8b की जगह। यह Concept 15 की three-question procedure को ऐसी चीज़ में बदलता है जिसे person task के बीच सच में कर सकता है।
Fallback line policy है। आपका GPU down या full हो, तो qwen3-8b की requests fail होने की जगह चुपचाप frontier-cheap पर जाती हैं। यह real trade है जिसे आप जानबूझकर चुन रहे हैं: money से खरीदी availability। इसे ऐसी जगह लिखें जहाँ future self पाए, क्योंकि भूला हुआ fallback ऐसा bill है जिसे समझ नहीं पाएँगे।
अब frontier menu को अलग limits दें, क्योंकि उसकी cost real money है:
curl -X POST http://localhost:4000/key/generate \
  -H "Authorization: Bearer $LITELLM_MASTER_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "user_id": "student-0417-frontier",
    "models": ["qwen3-8b", "frontier-cheap", "frontier"],
    "max_budget": 5.00,
    "budget_duration": "30d"
  }'
पीछे हटकर देखें कि क्या बनाया। One address। उसके पीछे आपके अपने hardware पर model और ऐसे clusters के models जिन्हें room में कोई कभी own नहीं कर सकता, same menu पर offer होते हैं, same caps के against billed होते हैं और same two settings से पहुँचते हैं। Concept 2 ने सिखाया था कि brain केवल address है। यह उसी sentence को उलटा पढ़ना है: एक address कितने भी brains छिपा सकता है, और उनके बीच choice अब किसी की config file है। आपकी।
आपका fallback failed लगभग sixty hours तक हर वह request जो free होती, paid cloud model पर run हुई और service perfectly काम करती रही, और ठीक इसी कारण किसी को पता नहीं चला। Fallbacks silently money को availability से trade करते हैं, और silence ही danger है। Two things add करें: vLLM container unhealthy होने पर alert और gateway पर spending alert। Fix fallback हटाना नहीं है। यह सुनिश्चित करना है कि कुछ minutes से longer fallback किसी को बताए।qwen3-8b requests को frontier-cheap पर भेजता है। Friday evening को driver update के लिए GPU machine reboot होती है और Monday तक किसी को पता नहीं चलता। Weekend में क्या हुआ और क्या add करना चाहिए?Answer देखें
Concept A5 तब done है जब: एक key local model और frontier model दोनों तक name से पहुँचे और समझा सकें कि fallback rule क्या ख़रीदता है और उसकी cost क्या है।
A6. इसे watch करें: health बताने वाले three numbers
जिस service को कोई watch नहीं कर रहा, वह quietly fail होती है। vLLM अपने numbers http://localhost:8000/metrics पर उस format में publish करता है जिसे Prometheus पढ़ता है, और standard picture Prometheus का उन्हें collect करना तथा Grafana का उन्हें draw करना है।
Day one पर इसकी ज़रूरत नहीं। यह जानना ज़रूरी है कि कौन-से three numbers matter करते हैं, क्योंकि student से पहले वे बताते हैं कि ग़लत क्या है:
- Queue depth: कितनी requests wait कर रही हैं। यह आपका single most useful number है, और Part 2 experiment live gauge बन गया है। Near zero का मतलब machine आसानी से चल रही है। चढ़कर ऊपर रहने का मतलब GPU ख़त्म हो गया, और second card, smaller model या class पर honest limit का समय है।
- Time to first token: कुछ दिखाई देने से पहले user कितनी देर wait करता है। हर individual person का experience ख़राब होने पर भी throughput wonderful दिख सकता है। Students असल में यही number feel करते हैं और total tokens-per-second figure ठीक इसी को छिपाता है।
- Use में GPU memory। Compute से पहले memory भरती है और भरने पर, कुछ broken दिखने से पहले performance गिरती है। Node की सारी memory quietly use करता model सबका experience degrade करता है, जबकि हर container अब भी healthy report करता है।
उनके साथ two things और बैठती हैं। Gateway का अपना spending dashboard, जहाँ unexpected bill को month end की जगह जल्दी पकड़ते हैं। और दोनों containers पर plain health check, क्योंकि "क्या यह up है" ऐसा question है जिसका answer machine से three in the morning चाहिए, student के message से नहीं।
Queue depth door की line है। Time to first token वह time है जितना हर diner food के लिए wait करता है। GPU memory बताती है kitchen कितनी full है। केवल total meals served देखता restaurant owner सबसे आख़िर में जानता है कि जगह बिखर रही है।
Concept A6 तब done है जब: अपनी आँखों से vLLM container पर /metrics load किया हो और बता सकें कि student के "आज slow feel हो रहा है" कहने पर three numbers में पहले कौन-सा check करेंगे।
A7. यह कब worthwhile है और कब graduate करना है
Concepts 7, 12 और 15 की spirit में honest accounting।
Mini cloud तब बनाएँ जब:
- आपके पास कई users और एक budget है। Classroom, bootcamp, department, small company। Fifty people को serve करता one GPU उनमें से किसी को मिलने वाला cheapest capable setup है, और gateway "fifty people" को chaotic की जगह safe बनाता है।
- Data बाहर नहीं जा सकता। Concept 15 का first question organizational scale पर answered, साथ में institution के लिए matter करने वाला extra piece: किसने क्या access किया दिखाने वाली audit trail।
- Moving world के आगे one stable address चाहिए। Models, prices और providers हर few weeks बदलते हैं। Students gateway पर point करें, तो two hundred लोगों से settings बदलवाने की जगह config file में वह churn absorb करते हैं।
- Loops पूरे day run करते हैं। बाद में मिलने वाले Loop Engineering agents हमेशा requests fire करते हैं। Per-token bill पर वह addition कभी नहीं रुकता। पहले से owned और saturated GPU पर एक और request की extra cost लगभग कुछ नहीं है।
इसे तब न बनाएँ जब:
- आप one person हैं। पूरा front of house आप हैं। Concept 11 की तरह direct vLLM use करें और यह appendix skip करें।
- Traffic छोटा और occasional है। Idle GPUs की cost busy ones जितनी ही है। Real daily traffic volume से नीचे Part 3 के through rent करना money और weekends दोनों पर जीतता है, और बहुत बड़े margin से जीतता है।
- कोई इसे own नहीं करता। यह वह failure है जिसे कोई plan नहीं करता। Mini cloud service है और टूटने पर services को responsible person चाहिए। वह person मौजूद न हो, तो holiday पर पहली बार down होते ही चीज़ मरती है और सबका trust ख़त्म होता है।
Docker Compose से आगे कब graduate करें। ऊपर का compose stack real service है और surprising number of students को carry करेगा, लेकिन यह हर चीज़ की एक copy वाली one machine है। इसमें autoscaling और किसी चीज़ की second copy नहीं। इसे outgrow करने पर rewrite नहीं करते: same pieces को Kubernetes पर move करते हैं। Two paths के names जानना उपयोगी है। vLLM production stack metrics, dashboards और cache reuse पहले से wired Helm chart देता है। KubeAI आगे जाकर models को Kubernetes resources की तरह manage करता है, नीचे vLLM और Ollama run करता है और chat UI bundle करता है, इसलिए इस appendix का बड़ा हिस्सा two Helm installs में collapse हो जाता है। इनमें से कोई gateway replace नहीं करता, क्योंकि कोई per-user keys और budgets नहीं करता। वह layer ठीक वहीं रहती है जहाँ रखी थी।
Honest limit, और वही जिस पर Part 2 ख़त्म हुआ। Gateway किसी wall को move नहीं करता। यह throughput improve नहीं करता और brain को smarter नहीं बनाता। यह fast brain को shareable बनाता है, जो अलग तरह की win है और अक्सर वही तय करती है कि room भर लोग AI use कर पाएँगे या नहीं।
Department forty staff के लिए private AI service चाहता है। कोई direct autoscaling और multi-node serving वाले Kubernetes पर जाने का proposal देता है, "ताकि बाद में दोबारा न करना पड़े।" इसके against argument क्या है? Forty users उसे comfortably fit होते हैं जिसे Docker Compose के पीछे one GPU serve कर सकता है, इसलिए Kubernetes आज setup के weeks और permanent operational burden की cost पर कुछ नहीं ख़रीदता। Upgrade path rewrite भी नहीं: load justify करे तो वही containers, वही gateway config और वही model Helm charts पर move होते हैं। इस month काम करने वाली चीज़ बनाएँ, real traffic measure करें और measurement को decide करने दें कि graduate कब करना है। सही question "क्या इसे outgrow करेंगे" नहीं बल्कि "इसके टूटने पर on call कौन है" है।Answer देखें
Concept A7 तब done है जब: अपनी situation के लिए दोनों sides argue कर सकें और gateway की improve न की जाने वाली one thing बता सकें।
Appendix A एक line में
Inference engine tokens serve करता है और gateway लोगों को serve करता है, और mini LLM cloud केवल वे two programs और keys रखने की जगह है। इसे तब बनाएँ जब कई mouths एक budget share करें। और notice करें कि असल में क्या किया है: आपके address पर point करने वाले हर person के लिए अब आप cloud हैं।
References
इस page के commands के primary sources ये हैं। वे तेज़ी से move करते हैं, इसलिए किसी specific flag, price या version पर depend होने से पहले live docs check करें।
Part 1: Local (Ollama)
- Ollama, desktop app (model download और chat करें, terminal के बिना)। https://ollama.com/blog/new-app और https://ollama.com/download
- Ollama,
ollama launch(local model पर coding agent wire और launch करने के लिए one command)। https://ollama.com/blog/launch और https://docs.ollama.com/integrations/claude-code - Ollama, Anthropic API compatibility (native endpoint जो no-proxy setup possible बनाता है)। https://ollama.com/blog/claude
- Ollama, context length और
num_ctx, VRAM-based defaults और coding agents के लिए 64K guidance। https://docs.ollama.com/context-length - Claude Code, Environment variables,
ANTHROPIC_BASE_URL,ANTHROPIC_AUTH_TOKENऔरAPI_TIMEOUT_MSके लिए। https://code.claude.com/docs/en/env-vars - OpenCode, Providers,
opencode.jsonprovider block और OpenAI-compatible endpoint के लिए। https://opencode.ai/docs/providers/ - Skills installer और GitHub CLI
gh skillcommands, skills install और publish करने के लिए। https://skills.sh/docs
Part 2: Server (vLLM)
- vLLM, documentation home (installing,
vllm serveऔर OpenAI-compatible server)। https://docs.vllm.ai - vLLM, Tool calling,
--enable-auto-tool-choiceऔर per model family tool-call parser के लिए। https://docs.vllm.ai/en/latest/features/tool_calling/ - vLLM, Claude Code integration, Anthropic Messages support और
ANTHROPIC_DEFAULT_*_MODELvariables के लिए। https://docs.vllm.ai/en/latest/serving/integrations/claude_code/ - Qwen, vLLM deployment guide, Qwen3 models serve करने और recommended parsers के लिए। https://qwen.readthedocs.io/en/latest/deployment/vllm.html
Part 3: Cloud (OpenRouter)
- OpenRouter, Claude Code integration, environment variables और Anthropic-compatible endpoint के लिए। https://openrouter.ai/docs/cookbook/coding-agents/claude-code-integration
- OpenRouter, Kimi K3 model page, live slug, price और providers के लिए। https://openrouter.ai/moonshotai/kimi-k3
- OpenRouter, DeepSeek V4 Pro model page, live slug, price और providers के लिए। https://openrouter.ai/deepseek/deepseek-v4-pro
- Moonshot AI, Kimi K3 technical blog, architecture, context window और serving recommendations के लिए। https://www.kimi.com/blog/kimi-k3
- DeepSeek, API pricing, current V4 Pro rates और cache-hit pricing के लिए। https://api-docs.deepseek.com
Concept 16: Claude Code Router
- Claude Code Router, router install करने,
ProvidersऔरRouterconfig, transformers औरccrcommands के लिए। https://github.com/musistudio/claude-code-router
Appendix A: Mini LLM cloud
- LiteLLM, proxy server documentation, config file, virtual keys, budgets और rate limits के लिए। https://docs.litellm.ai/docs/simple_proxy
- LiteLLM, virtual keys,
/key/generate,/key/info,/key/deleteऔर per-key model access के लिए। https://docs.litellm.ai/docs/proxy/virtual_keys - LiteLLM, budgets और rate limits,
max_budget,budget_durationऔरrpm_limitके लिए। https://docs.litellm.ai/docs/proxy/users - LiteLLM, reliability और fallbacks,
router_settingsfallback rules के लिए। https://docs.litellm.ai/docs/proxy/reliability - vLLM, Docker deployment, official
vllm/vllm-openaiimage और GPU runtime flags के लिए। https://docs.vllm.ai/en/latest/deployment/docker.html - vLLM, production metrics, Prometheus endpoint, queue depth और time to first token के लिए। https://docs.vllm.ai/en/latest/serving/metrics.html
- vLLM, production stack, Kubernetes upgrade path के routing, metrics और dashboards वाला Helm chart। https://github.com/vllm-project/production-stack
- KubeAI, Kubernetes के लिए AI inference operator, vLLM और Ollama पर models को Kubernetes resources की तरह manage करने के लिए। https://www.kubeai.org
- Open WebUI, documentation, chat interface और OpenAI-compatible endpoint से connect करने के लिए। https://docs.openwebui.com
- NVIDIA, Container Toolkit installation guide, Docker के अंदर GPU access के लिए required। https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html